You carry a per-member hit rate. It was computed over six years of disclosed trades, it looks stable, and it feeds a weight in your sleeve. Over those six years the member sat on three different committee configurations, lost a subcommittee, gained a seat on another, and spent two of the years in the majority and four in the minority.
That number is an average across three different data-generating processes. It is not wrong in the sense of being miscalculated. It is wrong in the sense that the quantity it estimates does not exist, because there is no single stable process it is the parameter of.
Why an assignment change is a structural break and not a covariate
The distinction matters because it determines the fix. If committee membership were a covariate you would add it to the model and move on. It is not a covariate, it is a change in the mechanism that generates the observations.
The reason is that committee position determines what a member sees, when they see it, and in which industries. Change the committee and you change the entire information set. Trades in the new jurisdiction now have a plausible channel that trades in the old jurisdiction have lost. The module treats this as first-order rather than incidental: committee fit is a documented input to the per-trade signal score, alongside politician history, size and timing, and the Heatmaps tab carries a dedicated Committee Correlation view. If committee fit is an input to the score, then a change in committee is a change in the score's own domain, and pooling across it is pooling across the input.
There is a second break embedded in the same event and it is easy to miss. Majority and minority status changes what a member controls rather than just what they observe. A chair sets an agenda. A ranking member does not. The same person on the same committee in two different sessions is arguably two different regimes.
The break dates are on a published calendar, which almost never happens
Structural break detection is normally a statistical problem. You run a changepoint test, you argue about the penalty term, and you accept that your break dates have confidence intervals wider than the regimes you are trying to separate.
Here you do not have that problem. Committee assignments change at known moments: the start of each new session, plus a modest number of mid-session changes when seats open. Those dates are public, published and unambiguous. You get the break dates handed to you, for free, in advance.
That is an unusual gift and it should change how much effort you spend. Build a table keyed by filer, committee, subcommittee, role and effective dates, sourced from the official record. It is a bounded piece of work, it updates on a predictable cycle, and it is the single asset that makes every downstream fix in this article possible. Without it you are inferring regimes from the data, which is both harder and worse.
One question to resolve before you use any committee-linked output from a vendor, this module included: is the committee relationship computed as of the trade date, or as of today? If historical trades are being scored against current assignments then the committee-fit input is misattributed for every trade that predates the current configuration, and in a direction that flatters recent regimes. I have not confirmed which convention the Committee Correlation view uses, and it is exactly the kind of thing to establish before a number from it appears in a model.
Segmenting per member destroys the sample, so raise the level of the estimate
Here is where the obvious fix fails. Suppose you take your per-member hit rate and split it at each reshuffle date. A typical low-cadence filer might disclose forty transactions across six years. Split into three committee regimes, that is thirteen observations per segment. A hit rate on thirteen observations has a standard error wide enough to contain almost any hypothesis you care to test.
So the segmentation is correct and unusable at the same time. Doing it honestly leaves you with nothing to estimate. Doing it dishonestly means pooling, which is where you started.
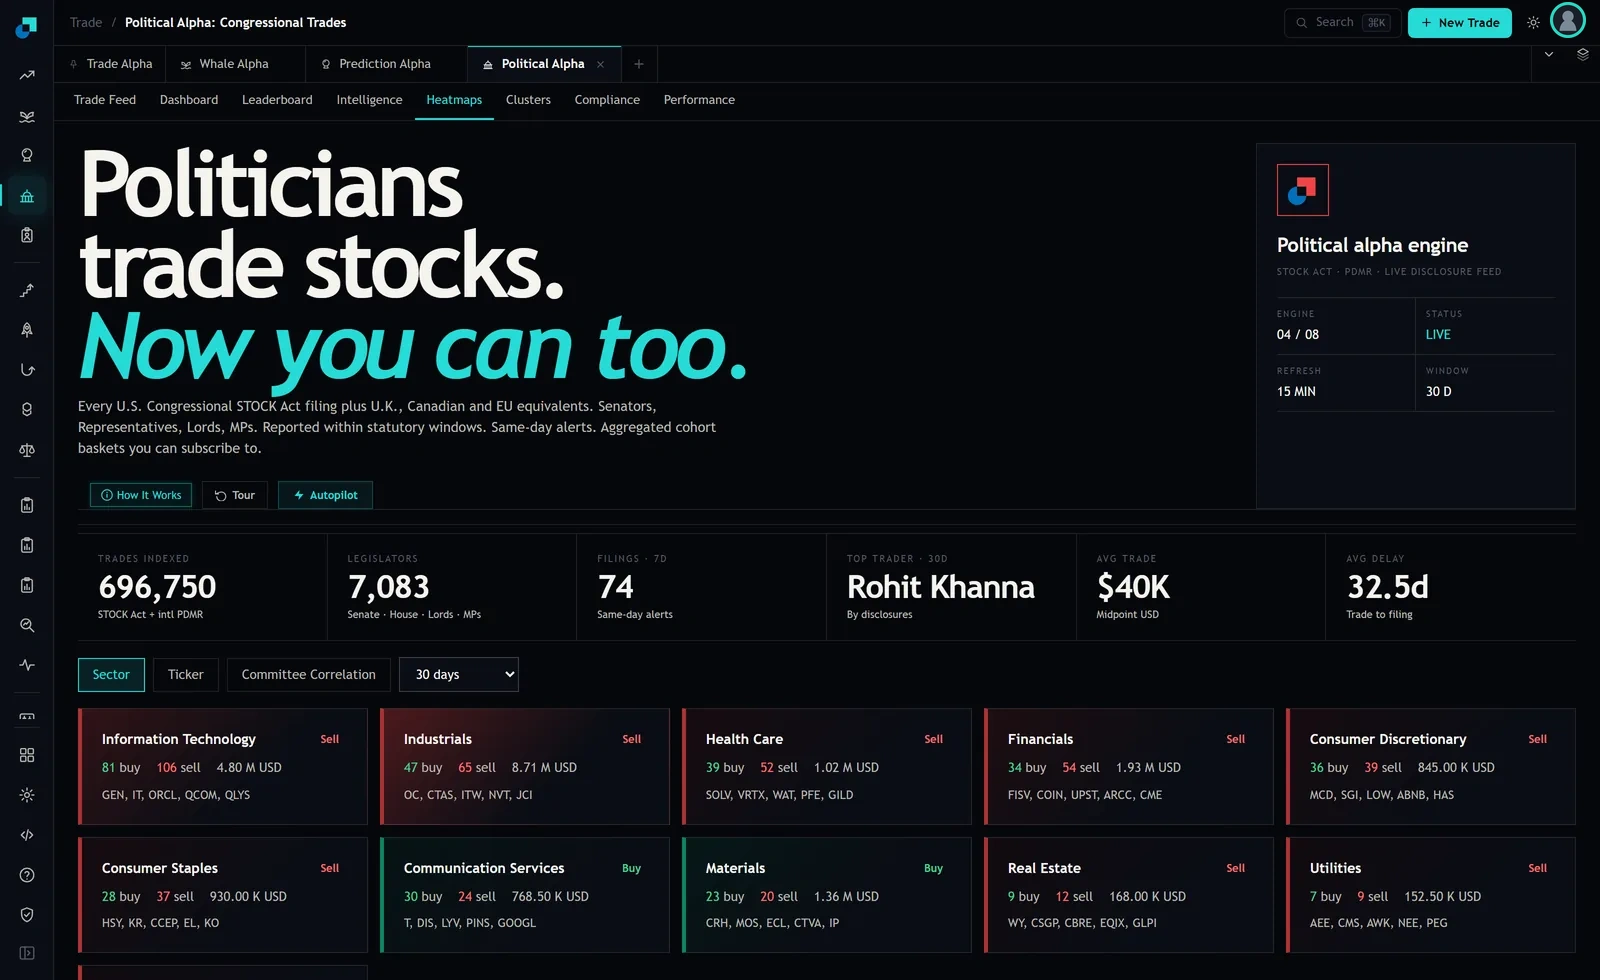
The resolution is to stop trying to estimate a per-member parameter at all and move the estimate up a level. The quantity you actually want is not "how good is this member" but "how do trades made inside committee jurisdiction differ from trades made outside it". That question pools across the whole population rather than within one filer, and the population is large: the Leaderboard reports 7083 politicians and the dashboard reports 696,750 indexed trades.
Constructed that way, a reshuffle stops being a problem and becomes the source of identification. Every reshuffle moves a member from one jurisdiction to another, which gives you the same person trading the same way under two different information regimes. That is a much better research design than anything you can build from a single member's pooled record, and it exists only because the reshuffles happen.
What the heatmap can and cannot be asked to do here
The Heatmaps tab is the aggregate flow instrument and it is worth being explicit about its shape, because the temptation is to use it for something it does not do.
What it gives you is a pooled cross-section. Three sub-tabs, Sector, Ticker and Committee Correlation, and a window selector reading 30 days on my capture. In the Sector view each tile carries a direction label, a buy count, a sell count, a notional and the leading tickers. Information Technology reads 81 buy against 106 sell on 4.80 M USD. Industrials reads 47 buy against 65 sell on 8.71 M USD. Health Care 39 against 52 on 1.02 M. Financials 34 against 54 on 1.93 M. Eight of the ten sector tiles carry a Sell label; only Communication Services at 30 buy against 24 sell and Materials at 23 against 20 carry Buy.
That is a snapshot of an entire population inside one window, which is precisely the aggregate you want for the cohort-level estimate described above. What it is not is a per-member time series. The only time control I can see is the window dropdown, so segmenting the history at arbitrary reshuffle dates is not something this view does for you. If you want that, you either capture the view on a schedule and build your own panel, or you pull the underlying trade records and do the segmentation in your own environment against your committee table. There is no third option that involves clicking something.
The maintenance calendar and the burn-in rule
Two operational consequences, and both belong in a written process rather than in someone's head.
First, the maintenance calendar. At the start of each new session, every per-member prior you hold expires. Not decays, expires. The correct action is to re-derive the committee table, re-map each filer to their new configuration, and re-run the cohort-level estimates with the new mapping. Schedule it as a task with a date rather than treating it as something that happens when someone notices. The dates are known years in advance, which removes every excuse.
Second, the burn-in rule. In the months immediately after a reshuffle you have no regime-specific evidence about a filer, because the new regime has produced almost no observations. The instinct is to fall back on the member's pooled history. That instinct is exactly backwards, because the pooled history is a measurement of regimes that no longer apply.
Fall back to the cohort prior instead. For a member newly seated on a committee with jurisdiction over a sector, the right expectation is the population-level relationship for that jurisdiction, not that individual's old numbers. As regime-specific observations accumulate you can shrink toward them, and a Bayesian update with the cohort estimate as the prior is the natural formulation. What you should never do is present a per-member statistic computed across a reshuffle to an investment committee without stating how many observations sit on each side of the break, because the moment somebody asks that question, and eventually somebody does, the answer determines whether the number meant anything.