Conviction on the Consensus board is a share of tracked dollars on one side of a market. It is computed correctly and labelled accurately, and it has one structural property that matters for anything downstream: it is invariant to how those dollars are distributed across wallets. Fourteen participants at equal size and one participant holding everything produce the same figure.
For a desk that ranks markets by conviction, or feeds it into a score, that invariance is not a cosmetic issue. It means the metric cannot distinguish between a cohort agreeing and an individual acting, and those two states have different forward properties, different capacity, and different behaviour when the position needs to come off.
What the board publishes and what it withholds
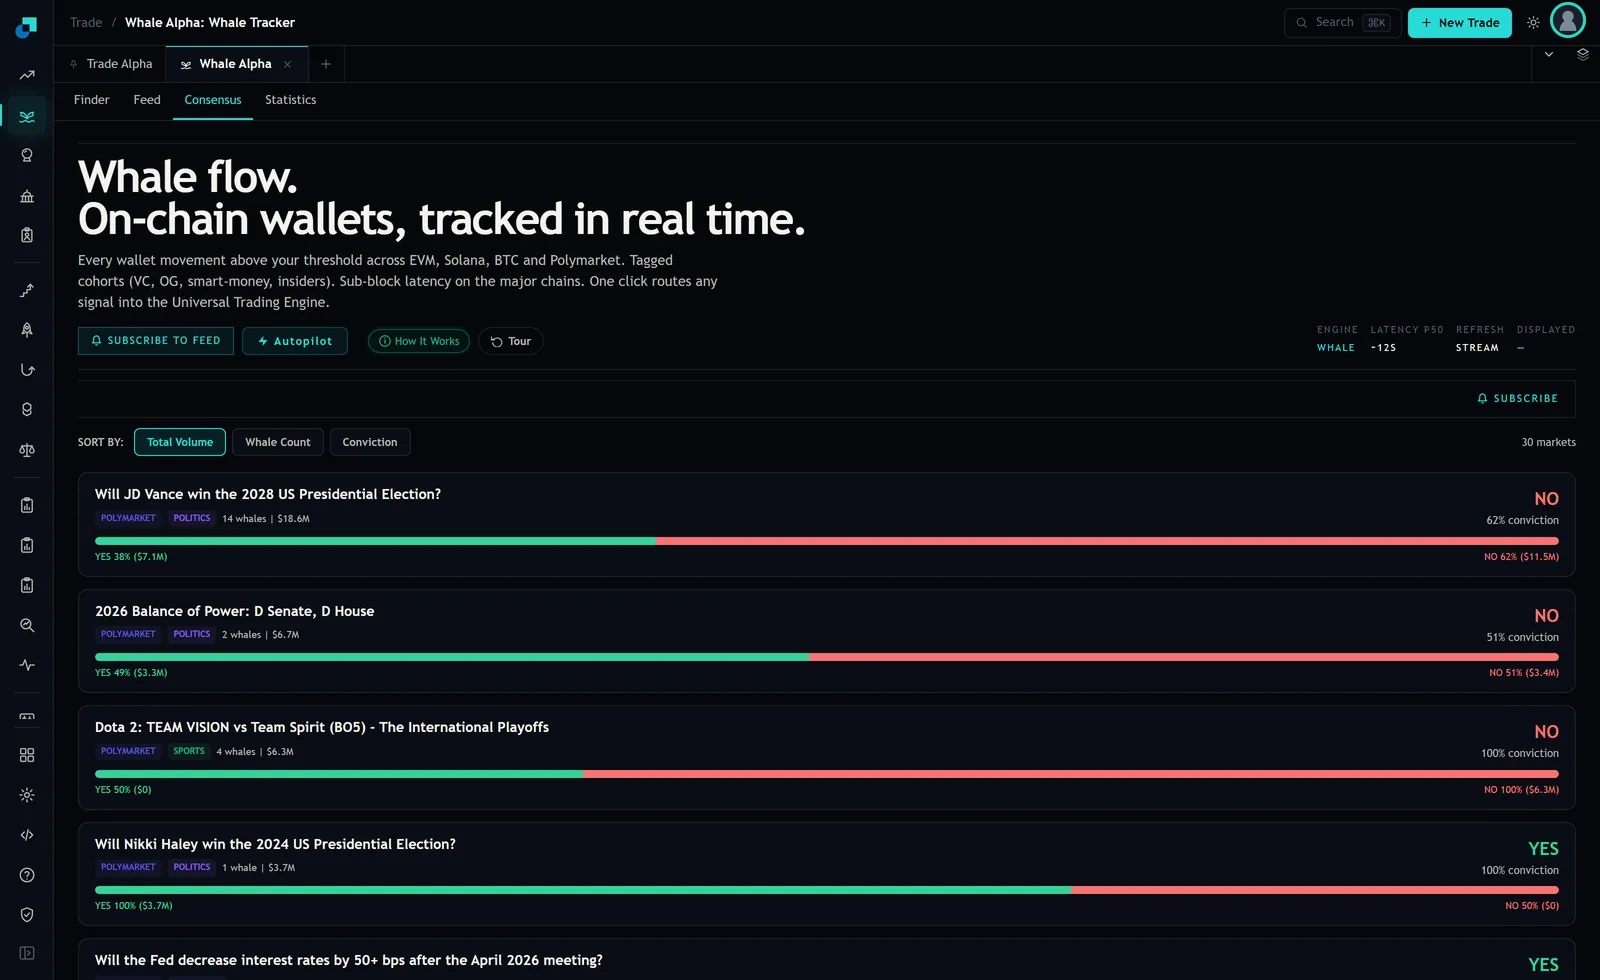
Each card carries three things you can use: a whale count, a total dollar figure, and the split of dollars across the two sides. At capture the board held 30 markets and could be sorted by total volume, whale count or conviction.
The four cards visible give the range. A 2028 presidential market showed 14 whales and 18.6 million dollars, NO at 62 percent conviction, with 7.1 million on YES and 11.5 million on NO. A 2026 balance of power market showed 2 whales and 6.7 million dollars, NO at 51 percent, split 3.3 against 3.4 million. An esports market showed 4 whales and 6.3 million dollars, NO at 100 percent conviction with zero dollars on the other side. A stale 2024 presidential question showed 1 whale and 3.7 million dollars at 100 percent YES.
What the board does not publish is the per-wallet dollar vector. You get the head count for the market and the dollar total for each side, but not how many of those heads sit on your side or what each of them holds. That gap is the design constraint, and any concentration term you build has to live inside it.
A Herfindahl term you can actually compute
The natural instrument is a Herfindahl index on the same-side dollar shares, with its reciprocal giving the effective number of participants. If one wallet holds everything, the index is 1 and the effective count is 1. If n wallets hold equal amounts, the index is 1 over n and the effective count is n.
You cannot calculate it from the card, because you do not have the shares. What you can calculate is a bound, and the bound is the useful object. The effective number of wallets on a side can never exceed the number of wallets on that side, which can never exceed the market's total whale count. So the card gives you a ceiling on breadth and never a measurement of it.
Treating the ceiling as the estimate is deliberately conservative in the wrong direction, which is fine as long as it is stated. It means your adjusted metric will flatter breadth, so any card that still looks concentrated after the adjustment is definitely concentrated. That is the property you want in a risk-facing metric: the errors run toward caution on the cards you reject and toward realism on the ones you keep.
The shrinkage form and what it does to the ranking
Multiply conviction by a shrinkage factor built from the breadth ceiling. With n as the market's whale count and k a constant the desk fixes in advance, the factor is n divided by the quantity n plus k. It approaches 1 for wide cards and collapses toward zero for narrow ones, with k setting where the collapse happens.
Fix k at 4 and run the four cards. The 2028 market gets 14 over 18, or 0.78, so 62 percent becomes 48. The balance of power market gets 2 over 6, or 0.33, so 51 percent becomes 17. The esports market gets 4 over 8, or 0.50, so 100 percent becomes 50. The stale 2024 question gets 1 over 5, or 0.20, so 100 percent becomes 20.
The ordering changes completely. Raw conviction ranks the two hundred-percent cards at the top, and both of them are single-side markets with tiny head counts. Adjusted, the widest card in the set moves to the front and the two dramatic ones fall to the middle and the bottom. That reordering is the entire value of the term, and you can see it on four cards without any infrastructure.
Choosing k is a governance decision, not a fitting exercise. It expresses how many participants you require before you are willing to treat a dollar share as a cohort statement. At k equals 4, a card needs 12 whales to retain three quarters of its raw conviction and 4 whales to retain half. Set it once, write down the reasoning, and do not touch it per market, because a k chosen after seeing the board is a k chosen to produce a conclusion.
Where the adjustment still lies to you
Four limits, and they belong in the metric definition rather than in a footnote.
The head count is per market, not per side. A card with 14 whales might have 13 on one side and 1 on the other, in which case the side you care about has a breadth ceiling of 1 while the card claims 14. This is the largest error in the whole construction. It argues for escalating any card that clears your adjusted threshold to a wallet-level pull from the Finder or the Feed before it supports a position, rather than trusting the adjusted figure on its own.
Independence is assumed and unverified. Fourteen wallets under one operator produce a breadth reading of 14 and a true effective count of 1. If you maintain an entity map, apply it before the count enters the formula. If you do not, the metric is measuring addresses, and the metric definition should say so in those words.
The cohort is not the market. Conviction is computed over tracked whale dollars, and the platform's statistics tab put the tracked population at 26,687 wallets. The rest of the book is outside the measurement, so a wide adjusted conviction is a statement about a sample whose selection rule you do not control.
And liveness is not checked anywhere in the formula. The 2024 presidential card was still on the board at capture, showing full conviction on 3.7 million dollars. Any composite that ingests conviction needs a liveness gate ahead of it, or it will happily rank a settled question above a live one.
How it enters the process
Keep the adjusted figure and the raw one side by side in the file, never the adjusted one alone. The gap between them is itself the finding: a card where the two figures nearly agree is broad, and a card where the adjusted figure is a third of the raw one is a single participant with a good graphic.
Record four fields per card at the time of reading: whale count, side dollars, raw conviction, and k. Those four reproduce the adjusted number exactly, which means the reading survives a change of formula later. A stored output that cannot be recomputed from stored inputs is the thing that makes a metric revision destroy a year of history, and this one costs four columns to avoid.