Most policy analysis on a desk is a restatement exercise. Somebody reads the statement, reads the minutes, listens to the press conference, and writes a paragraph that paraphrases what the committee said it cares about. That paragraph is not a model. It has no parameters, it cannot be scored, and when it turns out to be wrong there is nothing to update.
A fitted reaction function is a different object. It asks what weights on inflation and on labour market slack would have generated the sequence of decisions actually taken, and it produces numbers you can carry forward, test out of sample, and be shown to be wrong about. That last property is the reason to build one.
What the estimate is for, and what it is not for
The output is a mapping from economic conditions to a policy rate. Feed it your own forecast of inflation and unemployment and it returns an implied rate. Feed it consensus and it returns what the committee would do if consensus is right.
The value is entirely in the difference between that implied rate and what the market has priced. If they agree, the estimate has told you that the market's policy expectation is internally consistent with the committee's revealed behaviour, which is a useful null. If they disagree, you have a specific, decomposable question to answer: is the market expecting a departure from past behaviour, or is it carrying a different forecast of the inputs? Those are different trades and the estimate separates them.
What it is not for is prediction of the next decision in isolation. The residuals in this kind of estimation are large relative to a single meeting's typical move, and anyone presenting a point estimate for one meeting without the residual distribution alongside it is selling precision that the method does not produce.
The specification, and the three choices buried in it
The workhorse form regresses the policy rate on an intercept, an inflation term and a slack term, with a lag of the dependent variable to capture the well-documented tendency of committees to move gradually rather than jumping straight to a target level.
Three choices inside that sentence carry more weight than the estimation itself.
- The dependent variable. Levels with a lagged term, or changes. The level specification with smoothing is more standard and it produces a partial adjustment coefficient that is itself informative, but it also means most of the fit comes from the lag rather than from the economics. Report the estimate with and without the smoothing term so the committee can see how much of the story is inertia.
- The slack measure. Unemployment gap against an estimated longer run rate, an output gap, or a labour market composite. Each requires an unobservable that is estimated and revised, and the choice moves the coefficients materially. Fix it in writing and keep it fixed.
- The inflation measure and horizon. Realised twelve month, realised three month annualised, or a forecast. A committee that is genuinely forward-looking will be fitted badly by realised inflation, and a specification using forecasts requires you to decide whose forecast, which is a substantive choice rather than a technical one.
Real-time data or the estimate is worthless
This is the single largest failure in homemade reaction function work and it is fatal rather than cosmetic.
Macroeconomic series are revised, sometimes substantially and sometimes years later. If you estimate on the currently published history, you are asking what weights would explain the decisions given data the committee did not have when it decided. The resulting coefficients describe a committee with foresight, and the fit will look better than any honest version.
The correction is to use vintage data, meaning the values as first published at each decision date. Real-time vintage archives exist for the major series and they are not difficult to work with. The practical consequence is usually that the estimated response to slack weakens and the residuals widen, which is the truth rather than a degradation.
The same principle applies to the unobservables. If your slack measure depends on an estimated longer run unemployment rate, that estimate has itself been revised, and using today's version imports hindsight through a side door.
What breaks the estimate, and how to show it breaking
Four problems deserve explicit treatment in the write-up rather than a footnote.
Parameter instability is the first. Committees change composition, mandates get reinterpreted, and the framework itself is periodically revised. A single set of coefficients fitted across decades assumes a stability that plainly does not hold. Estimate on rolling windows, plot the coefficients over time, and let the instability be visible. A chart of a coefficient wandering is more honest and more useful than a table of one number with a standard error.
Censoring is the second. Any period where the policy rate sat at an effective floor is a period where the committee's desired rate was unobserved, because the instrument could not go where the reaction function wanted. Estimating through those windows with ordinary least squares biases the coefficients. Either exclude the censored periods and say so, or use a specification that handles the bound and a shadow rate series, and be explicit that the shadow rate is itself a model output with its own assumptions.
Endogeneity is the third. The committee reacts to conditions and conditions react to policy. Nothing in a simple regression separates those, so the coefficients are descriptive of a joint process rather than causal. That is acceptable for the use case, which is anticipating behaviour rather than establishing effects, but it must be stated so nobody downstream reads a coefficient as a policy multiplier.
Sample size is the fourth and it is the one people forget because the data looks plentiful. There are only a handful of decisions a year. A twenty year sample is well under two hundred observations, with high serial correlation, which means the effective information content is far smaller than the row count suggests. Standard errors computed without accounting for that will be too tight.
Scoring it against the curve rather than instead of it
Once the estimate exists, put it into a competition it can lose.
Each month, record three things: the market-implied path from the relevant rate futures or overnight index swaps, your model's implied rate at the same horizons given consensus inputs, and the eventual realised outcome. After a year you have a track record for the model and for the market on identical terms, and you can compute the model's incremental value rather than asserting it.
Decompose the disagreements. When your implied rate differs from the market, attribute the gap between two sources: a difference in the forecast inputs, which you can test by feeding the market's implied inputs into your model, and a difference in the mapping, which is what remains. Only the second is a genuine reaction function view. In my experience most apparent disagreements collapse into the first once you do the decomposition, and that finding is itself worth having because it stops the desk from taking a policy view when what it actually has is a growth view.
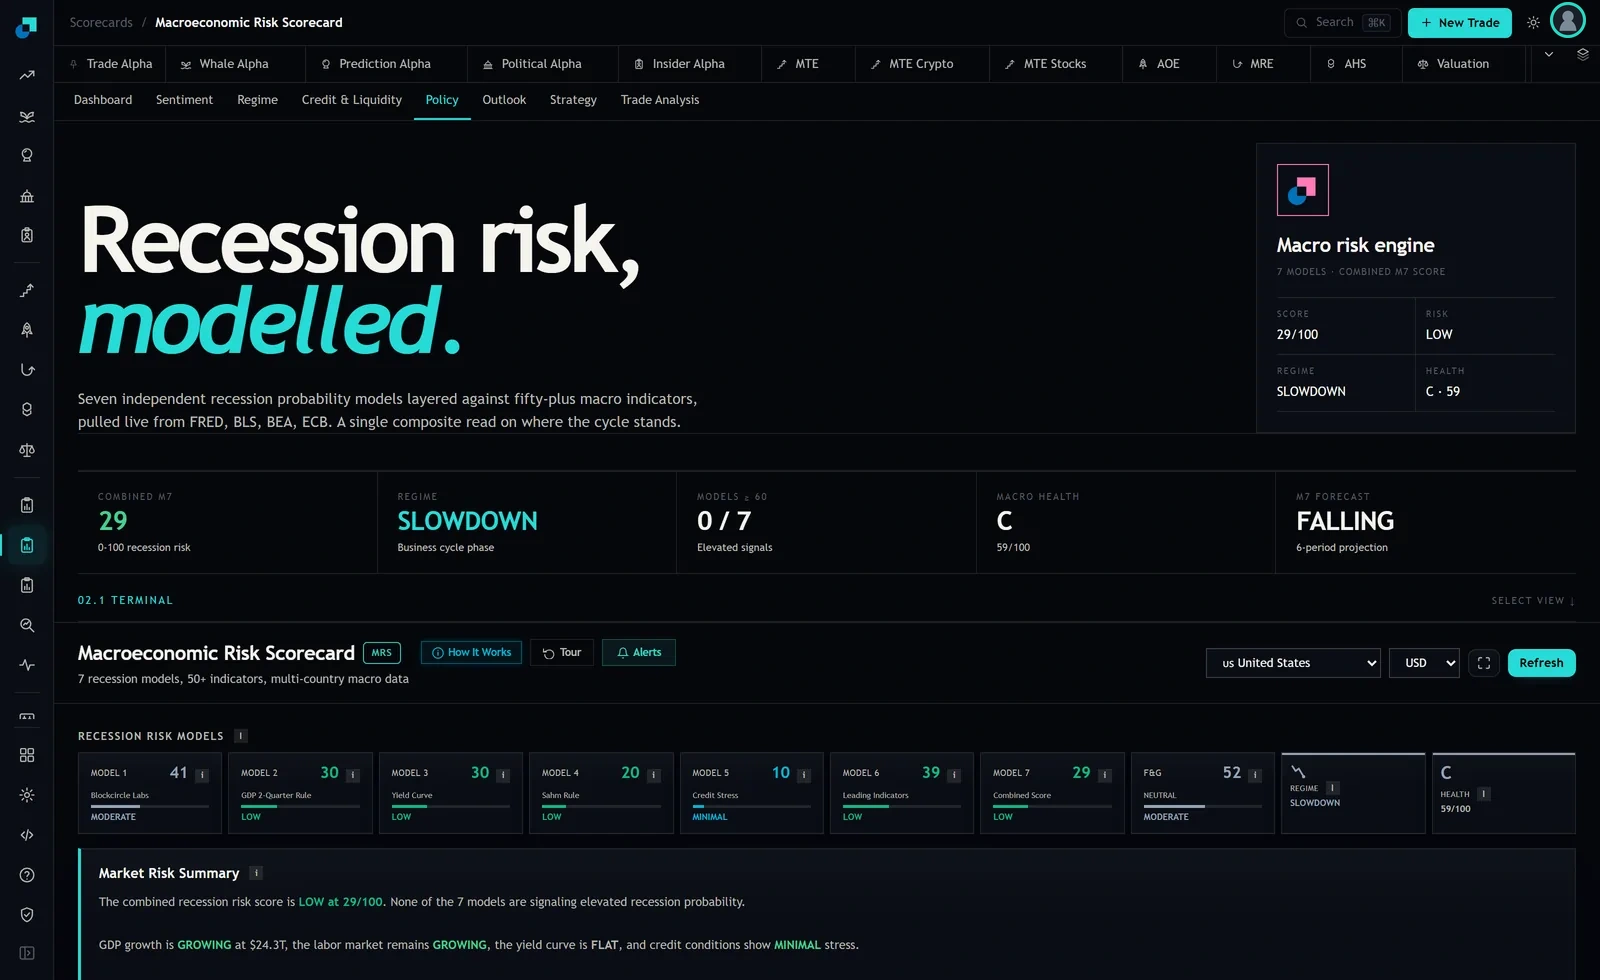
Keep the scorecard's own reads in the same pack for context rather than as inputs. The header currently shows a combined M7 of 29 out of 100 tagged LOW, a regime label of SLOWDOWN, macro health at C and 59, and 0 out of 7 models at or above 60. Those describe the conditions your reaction function maps from. Holding them side by side with the model's implied rate makes the chain from conditions to policy expectation legible to anyone reviewing the position, which is most of what documentation is for.