Every strategy you are shown is a maximum. Someone varied a lookback, a threshold and a stop multiple, computed a metric across the combinations, and published the best one. That is not a criticism, it is what research is. The question for an allocator is whether the published cell sits on a broad flat region of that surface or on a single spike surrounded by cells that lose money, and the published row cannot tell you which.
So make it a precondition. No plateau evidence, no funding, stated in the mandate in advance rather than negotiated after a good-looking tear sheet is on the table.
The single-row problem
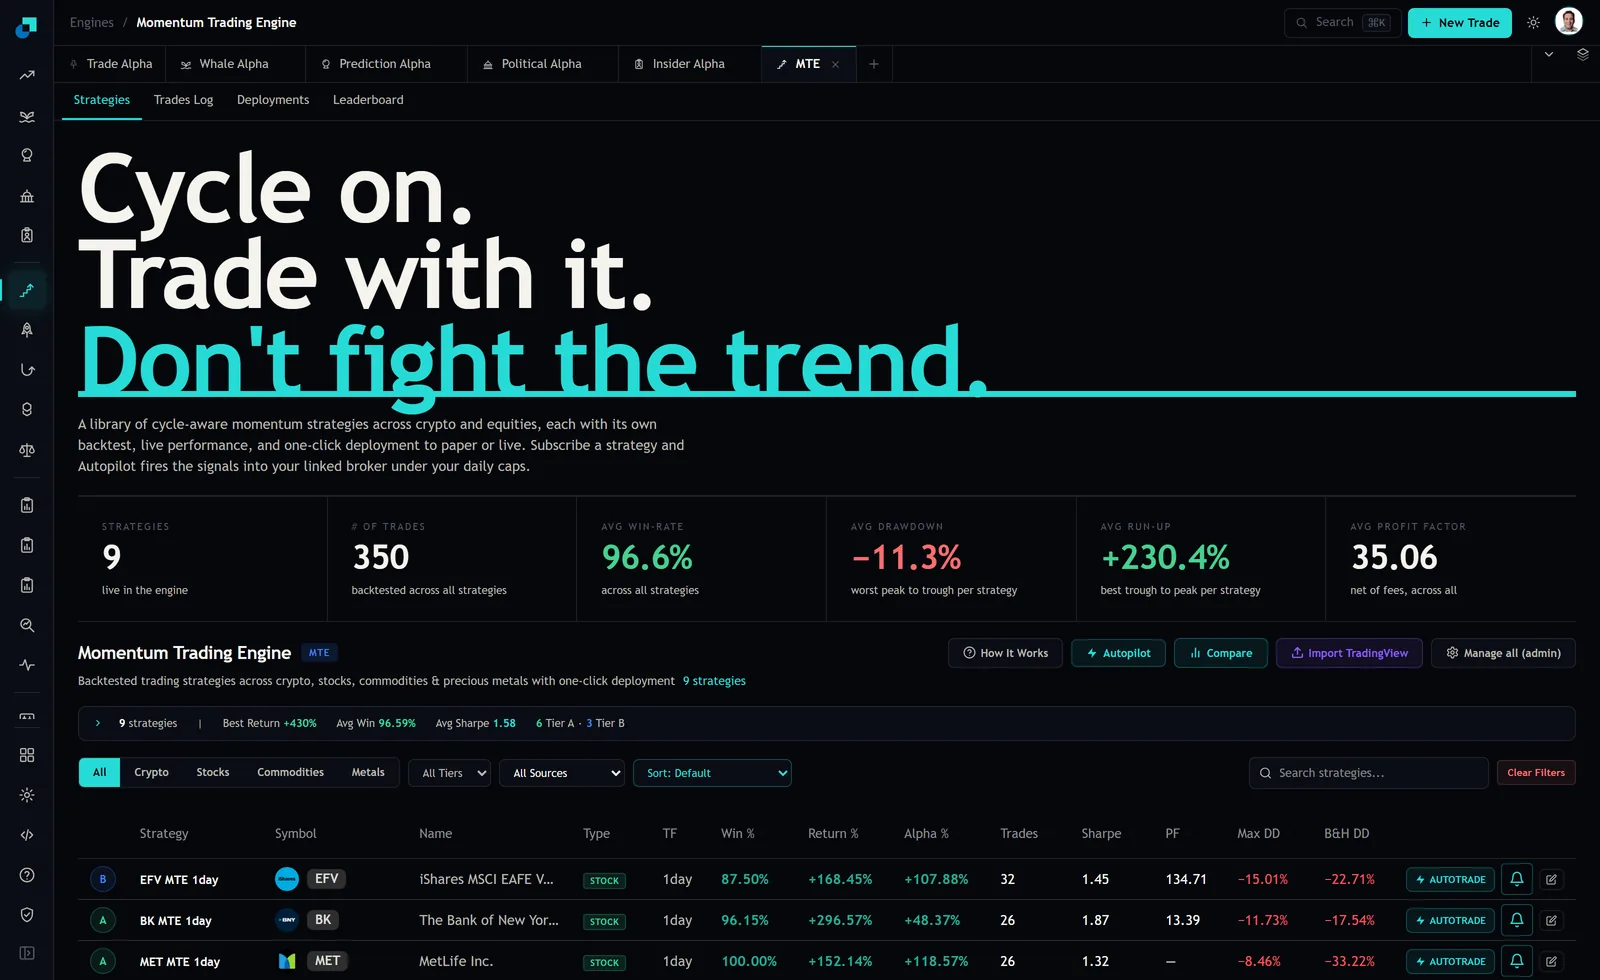
Look at what the strategies tab presents and the gap is obvious. Each configuration is one line: Strategy, Symbol, Name, Type, TF, Win percent, Return percent, Alpha percent, Trades, Sharpe, PF, Max DD and buy and hold drawdown, with a tier badge and an autotrade action. At capture the summary bar read 9 strategies, best return plus 430 percent, average win 96.59 percent, average Sharpe 1.58, split 6 Tier A and 3 Tier B, with filters for asset class, tier and source and a default sort.
Every field on that line describes the chosen cell. Nothing describes its neighbours. EFV MTE 1day reads a Sharpe of 1.45 on 32 trades and BK MTE 1day reads 1.87 on 26, and neither row tells you what the same configuration would have produced with the lookback moved by one step. I want to be plain about what I can and cannot see here: the captured surface presents a library of finished configurations, and I did not see a parameter sweep view or a sensitivity display on it. That is not a criticism of the product, which is a strategy library rather than a research environment. It is a statement about where the plateau evidence has to come from, which is a request you make, not a tab you open.
Plateau width has to be a number before you look at any surface
A plateau is only meaningful if you defined it before you saw the data. Write the rule into the diligence template in this form: the strategy's headline metric must remain within a stated fraction of its peak value across at least one grid step in every direction, on a grid whose step sizes are economically meaningful rather than decorative.
Three components, each of which someone will try to negotiate.
The tolerance. Requiring neighbours within 20 percent of the peak metric is a reasonable starting bar for a Sharpe or a profit factor and it is strict enough to fail a spike. State whether you mean the metric drops by no more than that fraction, and state which metric, because a surface that is flat in return is often not flat in drawdown.
The step size. A lookback grid of 19, 20 and 21 days is not a test of anything, since those three windows share almost every observation. Steps have to be large enough that the neighbouring configurations produce materially different trade sets. Roughly geometric spacing is the usual answer: 10, 20, 40, 80.
The dimensionality. The plateau must hold in every dimension you tuned, jointly, not one at a time. A surface that is flat along the lookback axis at the chosen stop multiple, and flat along the stop axis at the chosen lookback, can still be a narrow ridge. Ask for the joint grid.
Why the sample lengths here make the plateau non-negotiable
The engine reports 350 backtested trades across nine live strategies, and the visible rows carry trade counts of 26 and 32. Call it around 39 trades per strategy on average. That number governs everything.
The standard error of a Sharpe estimate over T observations is approximately the square root of one plus half the squared Sharpe, all divided by T. At the reported average Sharpe of 1.58 and 39 observations, that is the square root of 2.248 divided by 39, which is about 0.24. So each cell of a parameter grid carries roughly a quarter of a unit of noise on its Sharpe estimate.
Now consider a modest grid of ten lookbacks by ten stop multiples. That is 100 cells drawn from a noise distribution with a standard deviation of 0.24. The expected maximum of 100 such draws sits roughly 2.5 standard deviations above the mean, which is about 0.6 of a Sharpe unit of pure selection effect. A strategy with no edge whatsoever, evaluated over a grid of that size at that sample length, will produce a best cell near 0.6 and it will look like a discovery.
The plateau is the cheapest defence against exactly that, because noise does not have neighbours. A cell that is high because it drew favourable errors is surrounded by cells that did not. A cell that is high because the underlying effect is real degrades gently as you step away from it, since the neighbouring configurations capture most of the same trades for most of the same reasons. You do not need to know the true parameters. You only need the surface to be continuous.
Reading a surface someone else produced
You will usually be handed a picture rather than a grid. Four checks turn it back into evidence.
Ask for the full grid including the cells that lost money, exported as numbers. A heat map cropped to the profitable region hides the thing you are testing for. If the provider supplies only the top decile of configurations, the answer to the plateau question is that they declined to answer it.
Check the trade counts per cell, not just the metric. Neighbouring cells with wildly different trade counts mean the parameter step is changing what the strategy is rather than tuning it, and the plateau test does not apply across a discontinuity like that.
Confirm the metric is the one you asked for, computed net of the same cost assumption in every cell. A surface computed gross will be smoother than the same surface computed net, because costs bite hardest in the high turnover corner, and the shape can change materially.
And require the surface on data outside the estimation window. An in sample surface with a beautiful plateau tells you the fitting procedure is stable, which is a weaker claim than it sounds. The plateau you care about is the one that persists when the parameters meet observations nobody optimised on.
Fund the middle of the flat region, not the peak
The allocation consequence is the part that gets skipped, and it changes what you actually buy.
Take the parameters at the centre of the plateau rather than the argmax, even though the centre's backtested numbers are worse. The argmax is the cell whose estimate is most contaminated by favourable noise, so its expected forward performance is the lowest of any cell in the region, not the highest. This is uncomfortable to explain to a committee that has just seen the peak's numbers, which is why the plateau rule has to be written down before the meeting.
Then size the position on the plateau's worst cell, not its best. If the flat region contains a configuration with a maximum drawdown of 15 percent, that is your sizing input, because you have no basis for believing you selected the good end of a region you just declared to be statistically indistinguishable. And carry the plateau width forward into monitoring. If the strategy later needs a parameter change to keep working, the first question is whether the new value is still inside the region you funded. A change that walks off the plateau is not a tune, it is a different strategy arriving without an approval.