Somebody on every macro desk has been asked for the same table. Asset classes down the side, liquidity regimes across the top, mean return and volatility in the cells. It takes an afternoon to produce and it will be quoted in allocation discussions for years. The problem is not that it is hard to build. The problem is that the honest version of it has a column nobody wants to include, which is the number of independent regime spells each cell is standing on, and that number is almost always small enough to change what the table is allowed to say.
What the module gives you and what you have to construct
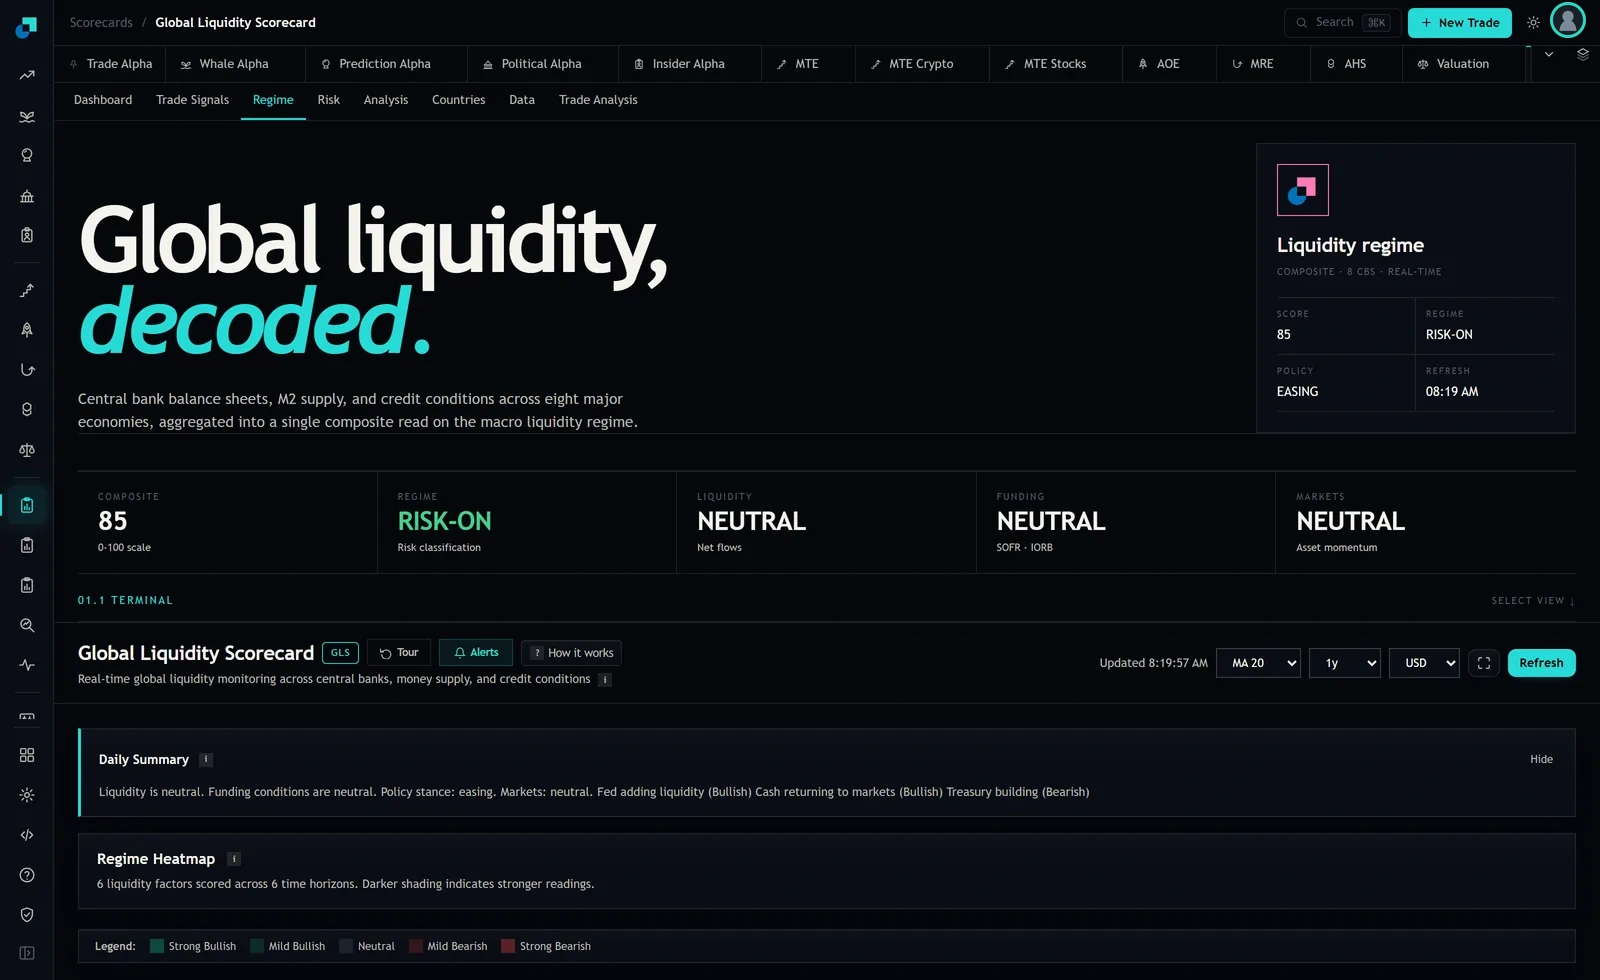
Start with what is actually on the screen, because the gap between that and a conditional return table is the whole project.
The Regime tab publishes a present-tense state. COMPOSITE 85 on a 0 to 100 scale. REGIME RISK-ON under the sub-label "Risk classification". LIQUIDITY NEUTRAL on net flows, FUNDING NEUTRAL on the SOFR and IORB relationship, MARKETS NEUTRAL on asset momentum. Below that a Daily Summary in sentences and a Regime Heatmap panel described as six liquidity factors scored across six time horizons on a five-level scale running from strong bullish to strong bearish. The header carries a window selector currently set to 1y, a moving average selector set to MA 20, and a base currency selector set to USD.
What none of that is, is a labelled state history. The tab strip includes a Data view, and the module publishes its input families at the family level, being aggregate central bank balance sheets across eight institutions, global M2, USD liquidity indicators and credit spreads. It does not publish the classification rule that maps those into the word on the screen. That single omission determines your entire method, because it means you cannot take the vendor's label as a historical series. You have to define your own state variable and be explicit that it is yours.
Defining a state variable you can defend in a review
Two routes, and the choice is not stylistic.
The first is to log the vendor's published label prospectively, one reading at a time, with the refresh stamp attached. This gives you a clean point-in-time series with no look-ahead whatsoever, and it gives you nothing for the period before you started. If you began logging this year, you have this year.
The second is to reconstruct a state variable from public inputs on a rule you write down and freeze before you look at returns. Bands on a composite you build yourself, or a simple sign-and-slope rule on aggregate balance sheets and money supply. This buys you history and imports two problems you have to disclose. Money supply and central bank balance sheet series are revised, so a reconstruction labels the past using data that did not exist at the time. And any rule you tune to produce interesting-looking regimes has been fitted to the sample you are about to test on.
The defensible construction is both. Reconstruct for history, log prospectively for validation, and report where the two disagree. Disagreement between your reconstruction and your live log during the overlap window is the most informative diagnostic in the whole exercise, and it is the first thing a competent reviewer will ask for.
Whichever route you take, fix the effective as-of date. A composite blending monthly money supply with daily credit spreads has a vintage governed by its slowest weighted input, not by its recompute stamp. If your state on a given day depends on a monthly series published with a lag, then aligning that state to same-day returns is a look-ahead error that will inflate every cell in your table.
The unit of observation is the spell, not the day
This is where most versions of this table quietly become fiction.
Suppose your history covers fifteen years of daily observations and your rule produces three states. You now have several thousand daily returns per state, which looks like an enormous sample and is not one. Liquidity regimes are persistent by construction. The state variable barely moves from day to day, so consecutive daily returns inside a spell are not independent draws from the conditional distribution. The effective sample size is closer to the number of distinct spells, and fifteen years of macro regimes might contain eight or ten of them in total, split unevenly across three states.
Three consequences follow, and all three belong in the output rather than in a footnote.
- Standard errors computed on daily observations are wrong by roughly the square root of the persistence, and no amount of heteroskedasticity and autocorrelation correction rescues a cell built on two spells. Correcting the standard error of a two-observation mean does not make it a mean.
- Report the spell count in the cell itself, next to the statistic, not in a caption. A cell reading "median 4.1 percent, 3 spells" is honest. The same cell reading "4.1 percent" with n equals 2,100 in the header is not.
- Bootstrap in blocks that respect spell boundaries, and report the width of the resulting interval rather than a point estimate. If the interval spans zero, say so in the table rather than in the discussion.
The table I would actually sign
Trim the statistics down to the ones that survive a small sample and drop the ones that do not.
| Column | Why it is there |
|---|---|
| Spells | The real sample size. Sorts the table by credibility before anyone reads a return. |
| Months in state | Shows how much of the sample sits in one long spell rather than several. |
| Median monthly return | Robust to the one spell that dominates the mean. |
| Interquartile range | Dispersion without pretending the distribution is normal. |
| Worst spell | The number the committee actually needs. Names the drawdown the state has produced at least once. |
| Hit rate across spells | How many spells were positive, expressed as a fraction of the spell count, not of the days. |
No means, no annualised Sharpe ratios, no t-statistics. Annualising a monthly figure derived from three spells produces a number with four significant figures and no content, and it is precisely that number that gets lifted out of the appendix and into a client deck.
The attribution question that decides whether the table is useful
Before the table goes anywhere, run the regression that tries to kill it.
Regime-conditional returns are frequently a restatement of something already in your risk model. If your liquidity state is correlated with the level or direction of policy rates, then a table showing that duration performs well in expansionary liquidity may be telling you nothing beyond the fact that duration performs well when rates fall. Regress your conditional returns on the factor exposures you already run, and report the residual. What is left after credit spread, duration and equity beta have taken their share is the marginal content of the liquidity state, and it is usually a good deal smaller than the raw table implies.
Do that work and the table changes character. It stops being a claim about what asset classes do in each regime and becomes a statement about how much of your existing factor exposure the liquidity state is already capturing. That is a less exciting finding and a far more usable one, because it tells you whether a liquidity overlay is adding an independent axis to the portfolio or double counting one you already own.
The version of this document that survives is the one where the sample-size column sits on the left, the residual attribution sits at the back, and the point estimates never appear without their spell counts attached.