The regime tab reports one word. Today it is SLOWDOWN, described underneath as the business cycle phase. That is a statement about the present, and a risk process does not consume statements about the present. It consumes distributions over what happens next, which is a different object and one you have to construct.
The construction is a transition matrix. Rows are the state you are in, columns are the state you are in at the next observation, and each cell holds the conditional probability of that move. Once you have it, the current regime stops being a label you describe in a commentary and becomes a row of numbers you can size against. That is the whole argument for doing the work, and the work is yours. The scorecard publishes the current phase. It does not publish a matrix, and nothing here describes a panel you can open.
What the module supplies and what you have to supply
What the module gives you is a consistently produced label. Seven recession probability models across more than fifty macroeconomic indicators from FRED, the BLS, the BEA and the ECB, resolving into a combined M7 score of 29 out of 100, a risk band of LOW, a macro health grade of C at 59 out of 100, and the phase word. There is also a counter of models at or above 60, currently 0 out of 7, and an M7 forecast tile reading FALLING described as a 6-period projection.
Consistency is the valuable property. A transition matrix is only meaningful if the state definition never moved, and a label produced the same way each period is exactly what that requirement demands. What you do not get is a history in a form you can regress on.
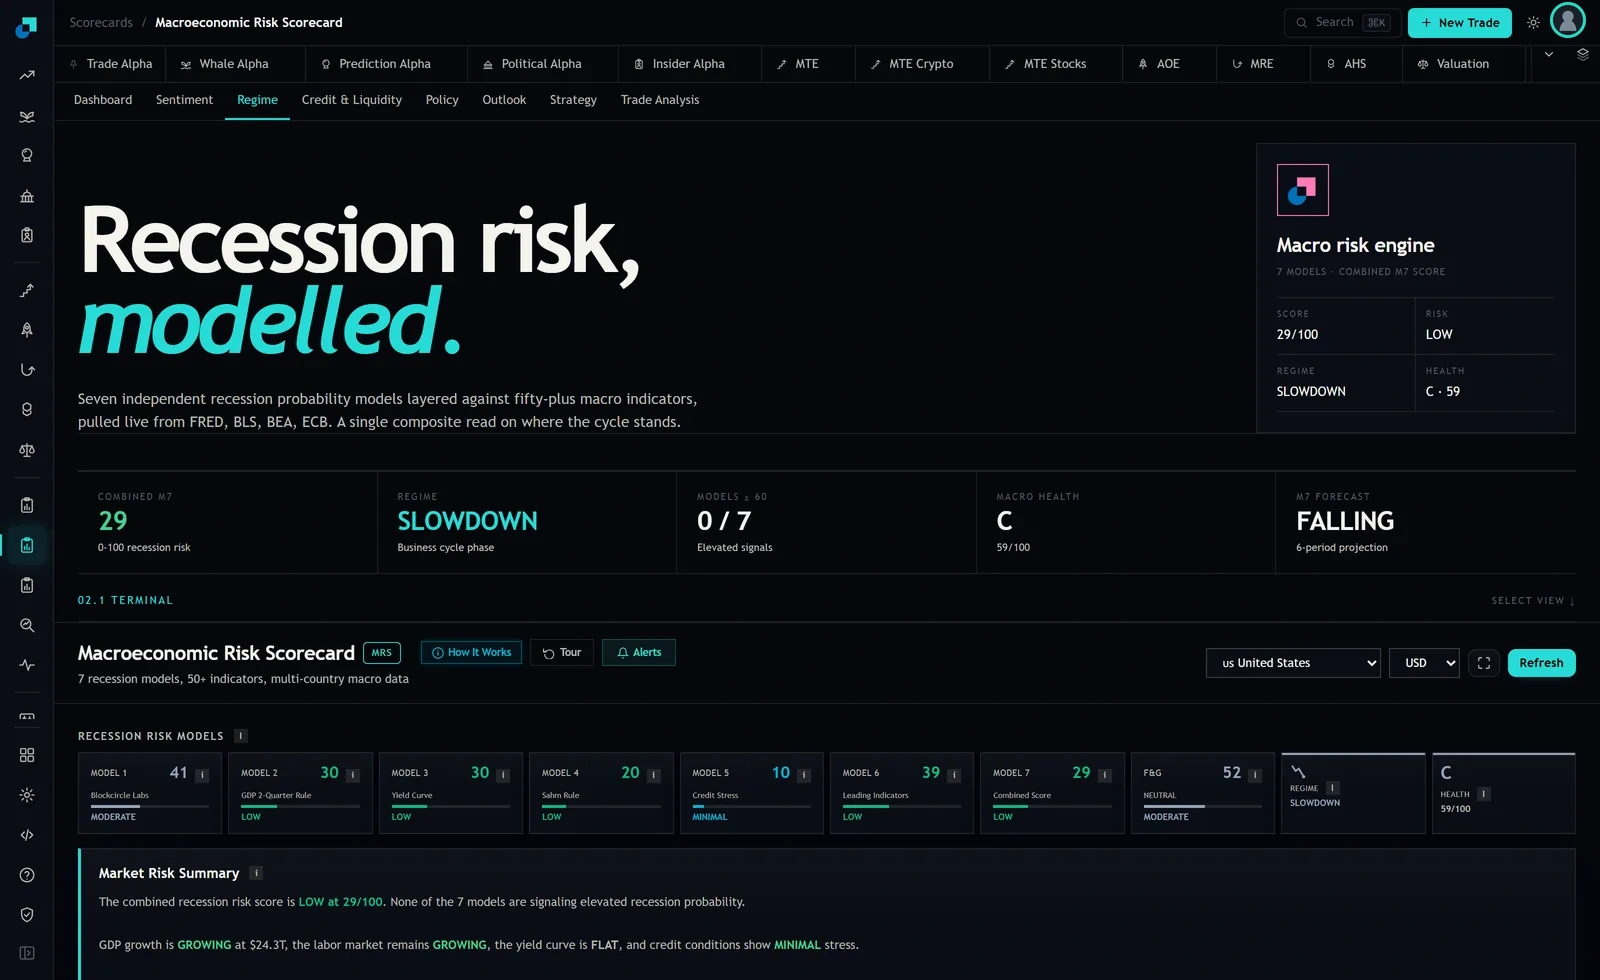
So the first practical step is unglamorous. Start logging. One dated row per observation period holding the phase label, the combined score, the health grade and the model counter. If you already run a monthly macro review, the labels may be sitting in your minutes, and pulling them into a spreadsheet is a morning of work.
Constructing the matrix without smuggling in look-ahead
The mechanics are simple enough to describe completely. Fix an observation frequency and never vary it. Monthly is the natural choice for a macro label, and it should be a fixed day of the month chosen in advance so that a busy month does not silently become a five week gap.
Take consecutive pairs of observations and increment the count in the cell indexed by the earlier label and the later label. That includes pairs where the label did not change, and those self-transitions are not filler, they are the persistence estimate and they carry most of the information in the matrix. Divide each row by its total and you have conditional probabilities.
Three things corrupt this quietly, and all three are avoidable.
- Relabelling history. If the methodology behind the label changes, or if you go back and correct an earlier label because you now know what happened, the series stops being a record of what you could have known and becomes a record of what turned out to be true. Every probability estimated from it is then optimistic in a way you cannot measure.
- Data vintages. The underlying statistics are revised. A label recomputed on final data is not the label that was on the screen at the time. If you can only reconstruct history on revised data, say so in the documentation and treat the matrix as indicative rather than as an estimate you would size against.
- Irregular sampling. Missing a month and then treating the next observation as adjacent understates persistence and overstates transition rates, because a two period move is being counted as a one period move.
The sample size problem, in numbers
This is where most transition matrix work quietly fails, so it is worth doing the arithmetic explicitly. The figures below are illustrative, chosen to show the shape of the estimation error rather than to report anything about this or any other series.
Suppose you have forty monthly observations in a given state and five of them were followed by a move to another state. Your point estimate for the monthly exit rate is 12.5 percent. The standard error on a proportion is the square root of p times one minus p over n, which here is the square root of 0.125 times 0.875 over 40, or about 5.2 percentage points. A rough ninety five percent interval therefore runs from roughly 2 percent to roughly 23 percent.
Sit with that range. Your estimate of the odds of leaving the current regime this month spans an order of magnitude. A sizing rule keyed to the point estimate is reporting a precision that does not exist, and two cells whose intervals overlap that heavily cannot be compared at all.
It gets worse in the corners. Transitions between states that rarely follow one another will have counts of zero or one, and a zero count is not evidence that the move cannot happen. Apply a smoothing prior so no cell is exactly zero, and document the prior, because it is doing real work in the output.
The honest summary is that a macro regime matrix estimated from your own history is a coarse instrument. It can support statements of the form "this state is more persistent than that one". It cannot support statements of the form "the exit probability is 12.5 percent", and the moment a number like that appears in a risk report without an interval next to it, somebody downstream will treat it as measured.
Reading the current row as a price of forward risk
Used within its tolerance, the matrix changes the question you ask, and that is where the value sits.
Without it, a regime overlay is reactive. The label changes, you respond, you pay the cost of responding and you accept whatever lag the label carries. With it, you can carry a standing view about the composition of the next period before anything changes. If the row for the current state puts meaningful weight on a specific adjacent state, then the hedges and the liquidity that state would require are things you can arrange now, at ordinary prices, rather than at the point where everyone else needs them too.
It is also the form in which a macro view survives a risk committee. A phase word invites a debate about whether the word is right, which is unresolvable and is the debate most macro meetings actually have. A row of probabilities with intervals attached invites two answerable questions instead: whether the estimate is well made, and whether the response is proportionate to it.
Set the matrix against your policy limits and you get a defensible sizing statement. If the current row puts most of its weight on persistence, and your process requires confirmation before you respond anyway, the expected cost of waiting is low relative to the cost of moving early. That is a sentence you can put in a memo.
Where the matrix is lying to you
Three assumptions are buried in the construction, and each is false to some degree.
The first is the Markov property, that the odds of your next state depend only on your current state. Real cycles have memory. How long you have already been in a state plausibly matters, and a plain matrix has thrown that away. Conditioning on time already spent in the state fixes it in principle and splits an already small sample, which usually makes the estimate worse. Choosing not to fix it is defensible. Not knowing it is there is not.
The second is stationarity. The matrix assumes the transition process is the same across the whole sample, and the structure of the economy over which these labels were generated has not been constant. If you weight recent observations more heavily to address that, you have shrunk the effective sample and widened the intervals that were already too wide.
The third is that the label is the state. It is not. The label is one model's estimate of a latent condition that nobody observes directly, and it carries its own error, which the matrix silently treats as zero. That error compounds with everything above.
None of this makes the exercise worthless. It makes it a low precision instrument, still better than the alternative of a single word on a tile and an argument about what it implies. Build the matrix, publish the intervals alongside it, and size as though the intervals are the real answer, because they are.