Confluence is the most persuasive idea in signal design and one of the easiest to overspend on. Every additional confirming condition sounds like it can only help, because each one removes trades that would have been wrong. The removed trades are visible in the log and the trades you never saw are not, which is exactly the asymmetry that produces overfiltered strategies with excellent hit rates and no positions.
The Market Reversal Engine already carries a good deal of confirmation before you touch it. Three scorecard inputs, AMS across 11 breadth and on-chain metrics, MMS across 6 timeframes, GLS across 8 central bank balance sheets, sitting behind a detector defined on RSI bands, Bollinger extremes, volume climax and key-level rejection. The question a desk faces is not whether confluence is good. It is whether the leg you are about to add on top of that stack is doing anything measurable.
A confirming leg buys exactly one thing
Strip the language away. A confirming leg is a binary filter applied to signals that have already fired. It passes some proportion of the reversals that were going to work and some proportion of the ones that were not. Call those two pass rates t and f.
The leg is informative if and only if t exceeds f. Their ratio is the entire value of the filter. A leg with t equal to f is a random sampler: it cuts your count, leaves your precision exactly where it was, and feels productive because the log now shows fewer losses in absolute terms.
The recall cost is unavoidable and exact. Adding the leg multiplies the number of real reversals you capture by t. There is no configuration in which this is free. So the decision is a comparison between a precision gain that depends on the ratio and a recall loss that is certain and equal to one minus t.
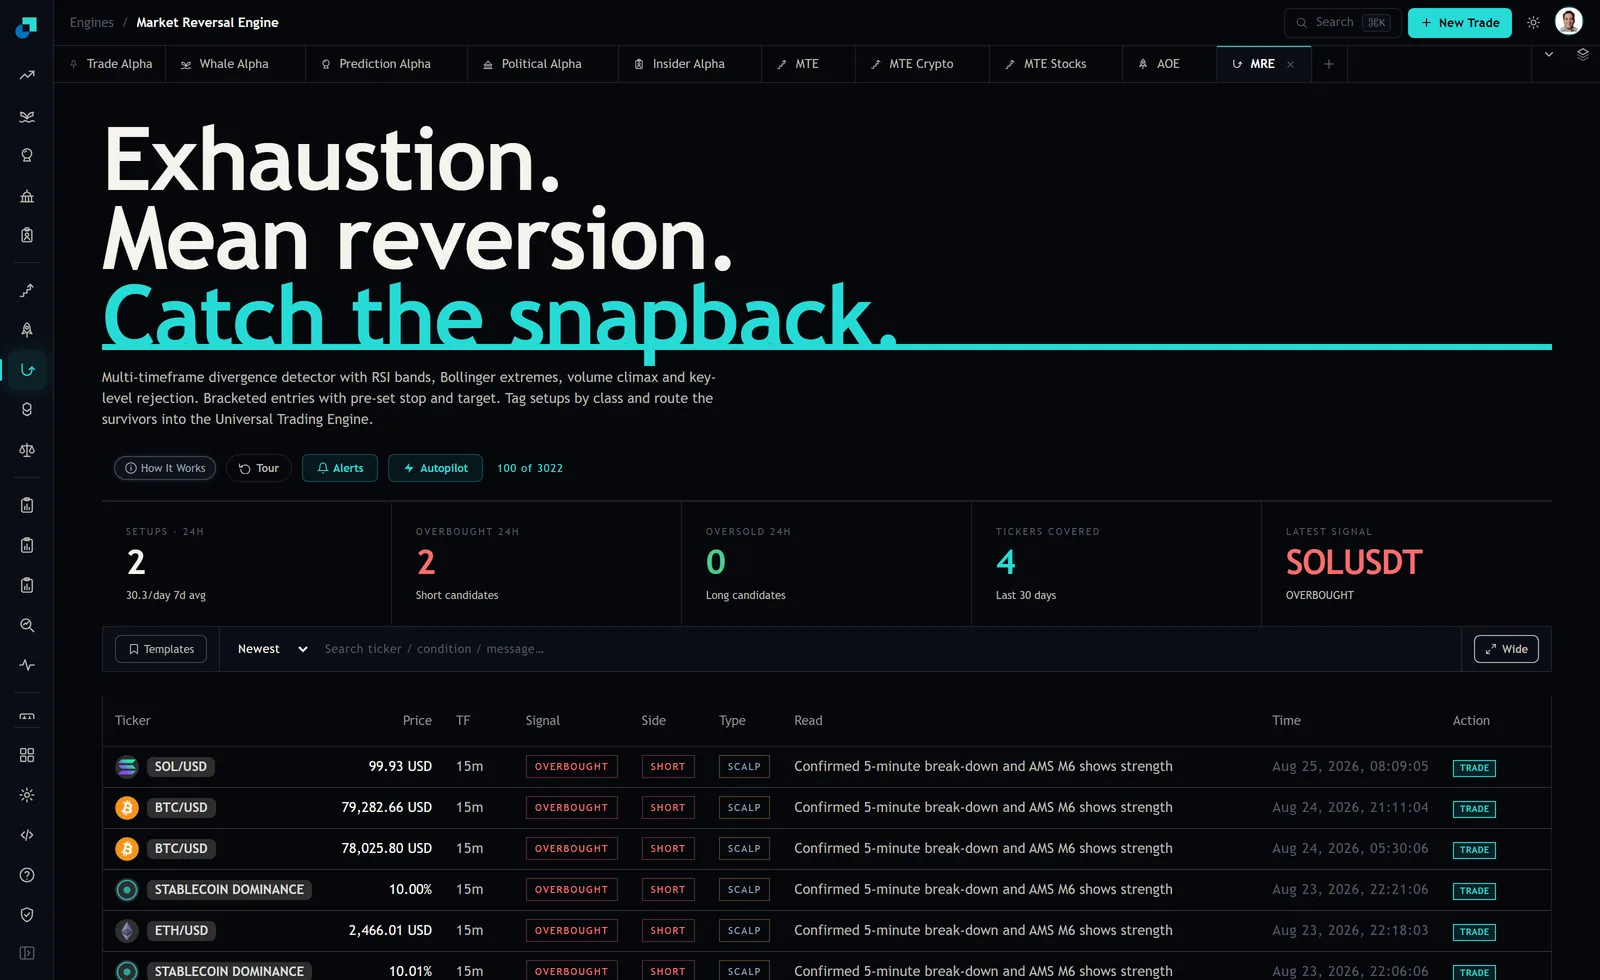
Look at what the Read column is telling you about the shape of the problem. The rows in the feed are not raw extremes. They are conjunctions, and every visible row carries the same conjunction. Your fourth leg is not being applied to the market, it is being applied to the residue of three prior filters, and the residue has different statistics from the market.
The survivor arithmetic, with placeholder inputs
Work it through with round numbers that are assumptions rather than measurements, because the structure is what matters and your own inputs will differ.
Suppose a base population of 1,000 signals per period, of which 300 are reversals that would have worked under your entry and exit rules. Precision is 30 percent. Add a leg with t of 0.8 on the workers and f of 0.5 on the rest. Survivors are 240 workers and 350 others, so precision rises from 30 percent to about 41 percent and recall falls to 80 percent. That is a good leg.
Add a second, similar leg. If it were independent, precision would climb again to about 52 percent with recall at 64 percent. Now add a third with the same headline pass rates. On paper, precision reaches roughly 62 percent and recall roughly 51 percent. Each step looks like progress and the count has halved.
The trouble is that the third and fourth legs almost never behave like the first. Their headline pass rates were measured on the original population. Applied to survivors, both t and f move toward each other, because the survivors are the signals that already looked good on every dimension the earlier legs measured, and correlated conditions agree with each other on exactly those cases. A leg whose standalone ratio is 1.6 can easily have a residual ratio near 1.05, at which point you are paying 20 percent of your reversals for a precision gain in the low single digits.
The measurement almost everyone gets wrong
This is the operational heart of it. Never evaluate a candidate leg on the full historical population. Evaluate it conditionally, on rows that passed everything already in production.
The procedure is mechanical. Take the archive of signals that fired under the current rule set. Label each one by whether it worked under your own entry and exit assumptions. Compute the candidate leg's pass rate separately within the workers and within the non-workers. Take the ratio. That number, not the standalone backtest, is what the leg is worth to you.
Then set a threshold on it in advance and hold to it. A residual ratio below roughly 1.2 is not worth the recall, and the exact cutoff should be derived from your own expectancy: the leg needs to raise expected value per opportunity net of the fact that you will have fewer opportunities. Deciding this after you have seen the result is how legs get added on the strength of a chart.
Sample exhaustion arrives before the curve does
There is a harder constraint that usually binds first, and it is arithmetic rather than statistical taste.
The archive control in the capture read 3,022 rows, and tickers covered read 4 over the last 30 days. Start from a few thousand rows. Collapse duplicates, because nested timeframes and clustered timestamps on the same instrument are not independent events, and the effective count falls hard. Apply three production legs, each keeping a fraction of what reached it, and the population available to test the fourth leg on is a small multiple of a hundred rows spread across a handful of instruments.
At that size, the confidence interval around your residual ratio comfortably contains 1. You are not measuring whether the fourth leg helps. You are measuring noise and naming it a decision. The honest statement in the research note is that the fourth leg's contribution is inside its own error bar, and the honest action is to leave it out, because a filter you cannot demonstrate is a filter that will be blamed for whatever happens next.
This is where the precision-recall framing quietly stops being the right tool. A precision-recall curve assumes you can estimate both coordinates at every operating point. Past the third leg on an archive this size, you cannot estimate either one to a useful tolerance, and the curve you draw is an interpolation dressed as evidence.
Spend the confirmation budget on sizing instead
The alternative to a fourth gate is not resignation. It is moving the information from the gate into the size.
A binary leg throws away everything except the pass or fail. The same underlying variable used as a continuous input to position size keeps the information and costs no recall at all, because every signal still gets taken, just at different weights. This has two properties a gate does not. It degrades gracefully when the variable turns out to be weak, since a near-flat weighting is close to equal sizing rather than a hole in your coverage. And it remains estimable on small samples, because you are fitting a monotone relationship rather than measuring a conditional rate in a shrinking cell.
The second place to spend is on the exit rather than the entry. Confirmation legs are entry-side by construction, and on a scalp-class signal with a bracketed stop and target, the distribution of outcomes is shaped as much by where those brackets sit as by which signals you took. Desks reach for a fourth entry filter partly because entry filters are the thing that is easy to backtest, which is a poor reason and a familiar one.
Then write down the count. Whatever the rule set is, state the expected number of positions per month it produces at your covered universe, and check it against the number the strategy needs to be worth running. A rule that is right on every signal it takes and takes six a year is not a strategy, it is an opinion with good manners.