Every model built on political disclosure carries an attribution assumption so basic that it usually goes unwritten: the person named on the filing is the person who made the decision. Drop that assumption and most of what the model is doing stops making sense, because the whole apparatus of committee fit, tenure weighting and per-filer history is an apparatus for reasoning about one individual's information set.
The assumption is wrong for a material share of rows, and it is wrong in a structured, detectable way rather than randomly. Disclosure regimes cover a household. Filings routed through a spouse's independently managed account arrive in the same feed, with the same fields, under the same name, and they carry a completely different kind of information.
What inverts is the inference, not the returns
Be precise about the claim, because the loose version of it is a performance assertion and I am not making one.
Consider a filer whose covered accounts include a professionally managed advisory book. That book rebalances on a schedule, holds funds alongside single names, spreads across sectors by construction, and generates transactions continuously. Now feed it into a scoring model. The trade count is high, so any activity-weighted measure ranks the filer near the top. The sector spread is broad, so a committee-fit term will find something in almost every jurisdiction. The transactions are frequent, so cluster detection has many opportunities to fire when the advisor happens to buy the same large-cap that other advisors are buying that quarter.
The model reads all of that as an engaged, wide-ranging, high-conviction filer. The correct reading is the opposite: this is the filer about whom individual filings tell you the least, because the named individual is furthest from the decision. Same inputs, inverted conclusion. That is the sense in which the signal flips, and it is an attribution failure rather than a return anomaly.
The second-order damage is worse than the first. A model fitted on a sample containing these rows learns a relationship between committee jurisdiction and trading that was in fact produced by advisory asset allocation, and it will keep asserting that relationship on new data.
The field you want does not appear on the row
The clean solution would be an ownership designation on each filing, letting you split the feed into filer, spouse, joint and dependent before anything reaches a model.
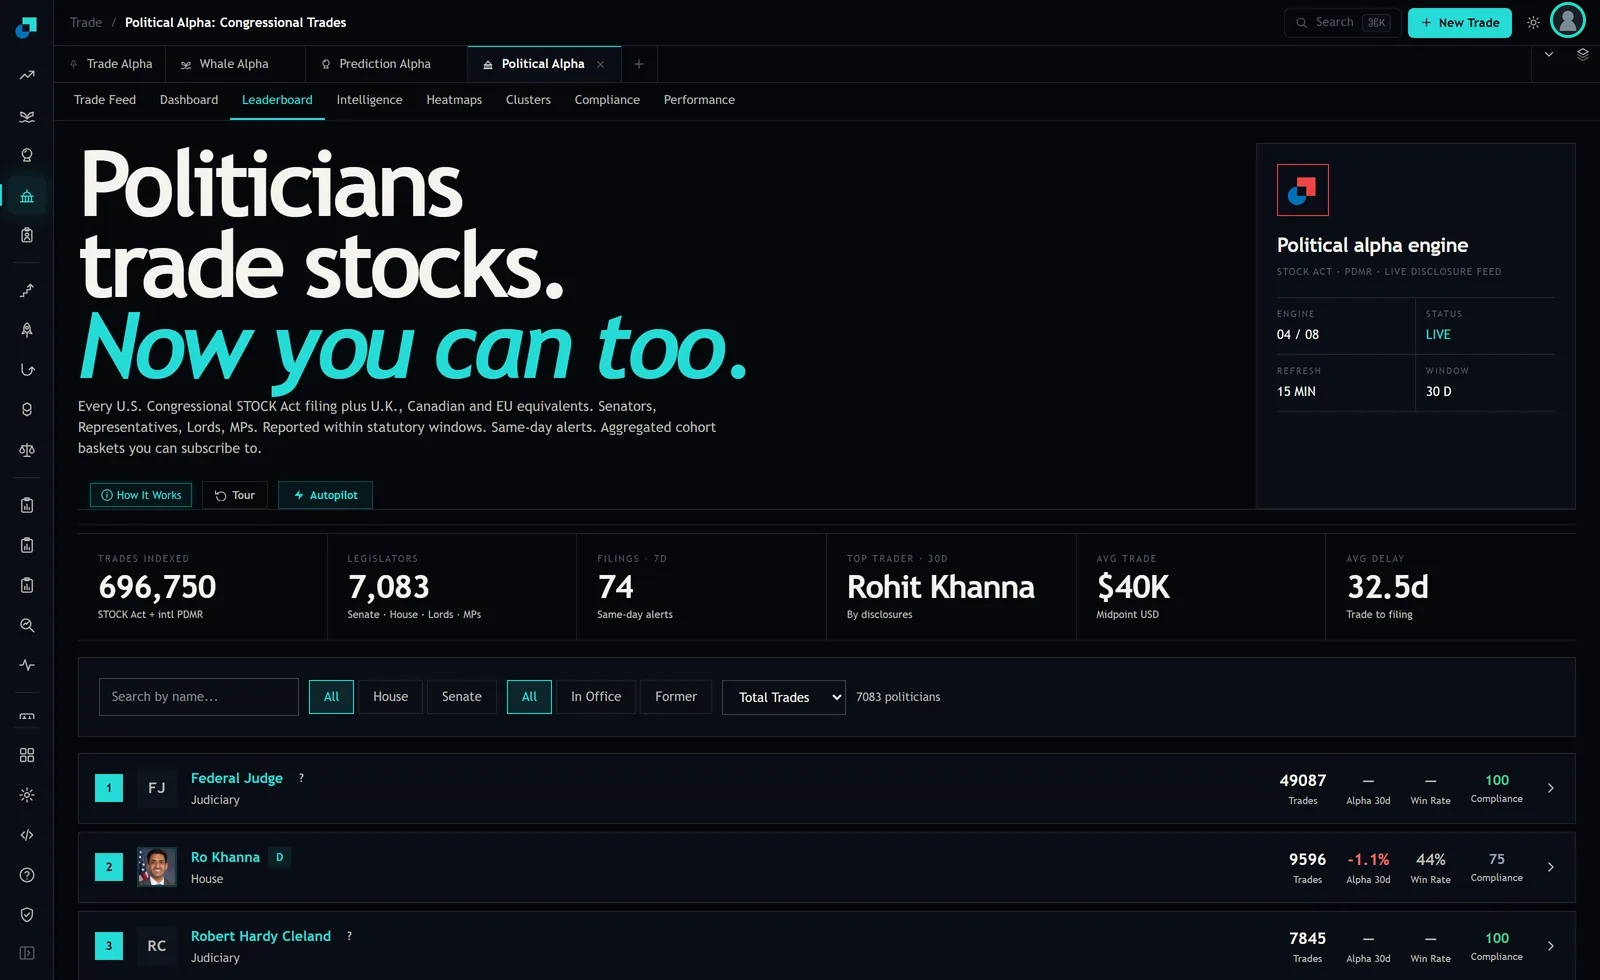
I cannot confirm that Political Alpha surfaces one. The Leaderboard row carries name, party badge, chamber, Trades, Alpha 30d, Win Rate and Compliance, and the filter bar offers search, chamber and status. None of that is an owner code. The module documents per-politician profile pages with full trade history, and it is entirely possible that ownership travels at the individual filing level inside them, but I am not going to assert a field I have not seen.
So treat this as the reader's decision rather than a product feature. Two paths. If your ingest can reach the underlying filing document, that is where an ownership designation would live, and resolving it at the source is worth more than any amount of inference from an aggregated row. If it cannot, you are building a probabilistic classifier from the fields you do have, and the rest of this is how I would specify it.
The flag set, and what each flag is actually detecting
Six flags, and they are deliberately redundant because no single one is decisive.
Breadth relative to count is the first. Compute distinct tickers divided by total transactions per filer. A discretionary book run by a person with views is narrow and repetitive. An advisory book is wide and touches each name once or twice. This ratio separates the two regimes better than raw count does, because raw count also picks up an active individual trader.
Instrument mix is the second and it is the strongest single flag available from a feed row. Look at the ticker forms. On the Dashboard tab, the live filing ticker on my capture ran four consecutive rows from the same filer, all sells, all carrying the same $1,001 to $15,000 bracket, across four different securities. One of those tickers had the five-letter form terminating in X that marks a US mutual fund share class, and only one of the four looked like an operating company. Four sells, one day, one filer, one bracket, a fund in the mix. That is not four opinions. That is a rebalance, and the pattern is legible from the feed alone.
Calendar regularity is the third. Bucket a filer's transactions by day of month and by proximity to quarter end. Advisory rebalancing clusters. Discretionary decisions do not, or at least not in the same shape.
Regime change is the fourth. Compute monthly transaction counts per filer over the full history and run a changepoint test. A step function in activity level, sustained afterwards, is consistent with an account being brought into or out of the covered population rather than with a change of mind.
Committee orthogonality is the fifth. The module carries a Committee Correlation view inside its Heatmaps tab, and committee fit is a documented input to the per-trade signal score. A filer whose sector distribution shows no relationship at all to their committee jurisdiction, while trading heavily, is more consistent with external allocation than with informed positioning.
Reporting latency is the sixth and the weakest, so use it only as corroboration. Externally managed accounts have a longer chain between a transaction occurring and a form being completed, so a persistently high trade-to-filing gap is mild evidence for the managed hypothesis. The population average sits at 32.5 days on the dashboard with 330 late filings in the window, and the Compliance column gives you a per-filer version of the same thing.
Classify the account, not the filing, and say which you did
An important design decision follows from the fact that these are inferential flags rather than a lookup. The classification is reliable at the filer level and unreliable at the individual filing level, because a filer with a managed spouse account may also make their own decisions, and those two streams arrive interleaved with no visible separator.
That asymmetry should drive the implementation. Score filers, not rows. A filer who trips four of the six flags goes into a managed-flow bucket and their entire stream is excluded from any conviction-weighted signal. A filer who trips one or two stays in the main sample. Trying to classify individual filings inside a mixed filer will produce a classifier that is right about the aggregate and wrong about most specific cases, which is the worst configuration for a signal that sizes positions.
Do not delete the flagged rows. They remain useful for aggregate flow work, where you want total buying and selling across a population and do not care who decided. The sector heatmap is exactly that kind of measurement. Deleting them makes your flow aggregates wrong in order to make your conviction signal right, and you can have both with a flag column.
What this costs when you get it wrong in either direction
Both errors have a price and they are not symmetric.
A false negative, meaning a managed book that stays in the conviction sample, contaminates the model quietly. It adds volume, so it gets weight. It adds breadth, so it appears in every sector bucket. It shows up in cluster detection by coincidence. You will not see it in the diagnostics because nothing about it looks anomalous.
A false positive, meaning a genuinely discretionary filer excluded as managed, costs you sample. That is visible, measurable and recoverable, since the flags are stored and you can re-run the study with the threshold moved.
Given that asymmetry, set the threshold to over-exclude. Four flags out of six is roughly where I would start, and I would rather lose a fifth of the discretionary population than carry advisory rebalancing into a signal that ends up sized against a mandate. Write the threshold and the six definitions into the sleeve documentation, along with the date the classifier was last re-run, because filer status changes and a classification made three years ago is a claim about a household that may no longer be true.