The risk report says the book holds a dozen distinct positions across four asset classes and the covariance matrix agrees, returning a portfolio volatility comfortably below the weighted average of the sleeves. Then a funding shock arrives, the sleeves move together, and the realised drawdown lands well outside the interval the report implied. Nothing in the model was wrong. The matrix was estimated on a full sample, which describes an average of several distinct environments, and averages are exactly the wrong object when the thing you are managing is the tail.
The number of bets you own is a conditional quantity
Start with the quantity that should sit at the top of the risk report and usually does not. Take the correlation matrix of your sleeve returns, compute its eigenvalues, normalise them to sum to one, and take the exponential of the entropy of that distribution. What comes back is the effective number of independent bets in the book. A twelve-sleeve portfolio with an effective number near ten is genuinely diversified. The same twelve sleeves with an effective number near three is a concentrated position wearing twelve names.
The important property of that statistic is that it is not a property of the portfolio. It is a property of the portfolio and the environment jointly. The same weights, the same instruments and the same mandate produce a materially different effective bet count depending on which correlation matrix you feed in. Reporting one number without naming the conditioning environment is reporting an average across worlds.
The structural reason this matters for a liquidity framework specifically is the mechanism behind cross-asset correlation in a contraction. When funding tightens, positions get closed for reasons unrelated to any view on the individual assets, because what gets sold in a margin event is what can be sold. That mechanism operates across sleeves simultaneously and it is indifferent to the fundamental independence you built the book around. It is the long-standing observation in the risk literature that diversification thins out precisely when it is needed, and the honest version of that observation is mechanical rather than mystical.
Conditioning on a published label instead of on realised returns
The tempting way to build a stress-conditional matrix is to select the worst return months in the sample and estimate on those. Do not. Selecting periods on the dependent variable guarantees a high measured correlation whether or not any regime effect exists, because you have conditioned on a common outcome and induced the very dependence you are trying to measure.
The fix is to condition on a variable that is external to your returns. The Global Liquidity Scorecard regime classification is a reasonable candidate for exactly one reason: it is defined outside your book and it does not change based on how your year went. At capture the tab was showing composite 85 on a 0 to 100 scale with a regime read of RISK-ON and a policy read of EASING, alongside component reads of LIQUIDITY NEUTRAL on net flows, FUNDING NEUTRAL on the SOFR and IORB relationship, and MARKETS NEUTRAL on asset momentum. Those are the fields that go into the conditioning column.
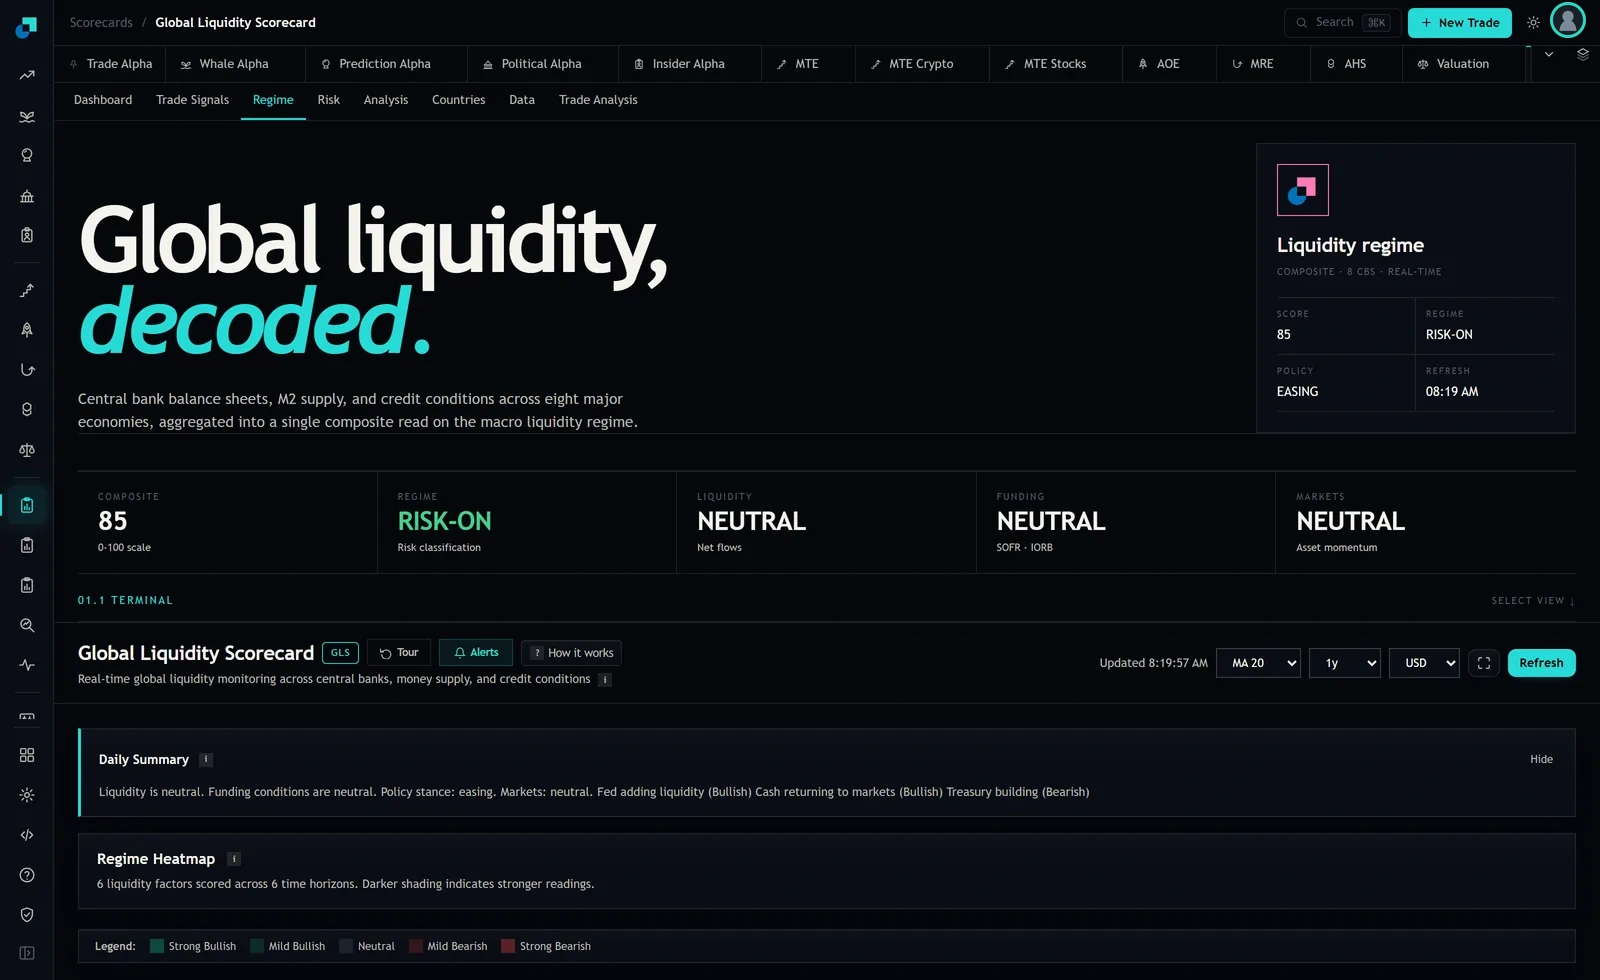
One caveat you have to write into the method note. The module publishes its inputs and its output but not its weights, so the conditioning variable is an index rather than an equation you can reconstruct. That is acceptable for this purpose, and it is worth saying explicitly in the documentation so that nobody later mistakes the label for something they can decompose.
The sample problem that makes conditional matrices lie
Splitting a sample by regime is arithmetically trivial and statistically brutal, and this is where most implementations quietly break.
Count the observations before you compute anything. If your sample is five years of monthly returns and the contraction state occupies a fifth of it, the stressed matrix is estimated on roughly twelve observations. For a twelve-sleeve book that means estimating sixty-six pairwise correlations from twelve data points, which is not an estimate, it is noise with a decimal point. The eigenvalue spectrum of a near-singular sample matrix will happily report a collapsed effective bet count regardless of whether any collapse occurred.
Three ways to make it tractable, in order of how much I would rely on them. Reduce dimensionality first: run the conditional estimate on four or five sleeve aggregates rather than every line, because the question is about diversification across risk sources rather than across tickers. Shrink second: apply a shrinkage estimator toward a structured target and report the intensity used, since an unshrunk conditional matrix on a short sample is not reportable. Move to higher frequency third, with the caveat that daily data buys observations at the cost of introducing asynchronous pricing and microstructure noise that will bias correlations downward across sleeves that trade in different sessions.
Then run the null. Randomly relabel the regime states, re-estimate, and repeat enough times to build a distribution of effective bet counts under no regime effect. If your actual conditional estimate sits inside that distribution, you have not found a regime effect, you have found a small sample. That test takes an afternoon and it prevents a class of confident wrong statements in front of a committee.
What changes once the conditional number is on the report
The purpose of this exercise is not the number, it is the two or three decisions the number should change.
Risk limits become conditional. If the effective bet count falls materially in a contraction state, then a gross exposure limit calibrated on the unconditional matrix implicitly permits far more concentrated risk in exactly the state where you can least afford it. State the limit as a function of the regime, so the book de-grosses on the conditioning variable rather than on the drawdown.
Hedge selection changes. A hedge chosen for its unconditional correlation to the book may have a much weaker relationship in the state you are hedging against. Evaluate candidate hedges on the conditional matrix, and be prepared to accept a hedge that looks inefficient on the full sample because it holds up in the state that matters.
Attribution language changes. When a drawdown arrives, the review question is whether the loss came from positions the process should have avoided or from a correlation regime the process had already documented. A conditional matrix in the file six months before the event is the difference between those two answers, and it is worth more in that meeting than any amount of retrospective explanation.
Where this framework stops being reliable
Three honest limits, all worth stating in the method note rather than discovering later.
The conditioning variable is contemporaneous. A regime label describes present conditions and carries no claim to lead anything, so this framework tells you the correlation structure associated with a state, not the state that is coming. Using it as a forecast is a category error the module never invited.
Regime boundaries are not clean. Transitions occupy real time, and observations near a boundary belong partly to both samples. Dropping a buffer of observations around each transition costs you sample you cannot afford and keeping them contaminates both matrices. Pick one, document it, and check that your conclusion survives the other choice.
And correlation is not the whole failure. In a genuine funding event the binding constraint is often the ability to transact at all, which no correlation matrix represents. A book that is diversified in covariance terms and concentrated in liquidation terms will still fail, and the second exposure has to be measured separately, in days to liquidate at a stated participation rate, next to the effective bet count rather than instead of it.