A policy component built on the level of rates has a specific and predictable defect. It stays elevated for as long as rates are elevated, which means it keeps signalling risk long after every participant has adjusted to the stance and every asset has repriced. The component is not wrong about the level. It is answering a question nobody in a portfolio context is asking, because a fully absorbed stance is not a risk, it is a condition.
The alternative is to score the gap between what was delivered and what was priced. A surprise measure has the property the level measure lacks: it goes quiet when nothing new is happening, and it moves when the market's expectation is falsified. That is the behaviour you want from a risk component.
What a level component is actually telling you
Consider the arithmetic of absorption. When a policy path is priced, the implied forward rates are in the discount function, every liability-driven investor has reset their hedges against it, and every borrower has refinanced or decided not to. The stance is embedded. It continues to have economic effects, which is why an outcome-based model such as a credit or labour market model will keep registering them, but it no longer represents new information.
A level-based component conflates those two things. It reports high readings for the whole duration of a tight stance, which produces two failures at once: a long run of readings that produce no action, followed by no distinction at all on the day the path is genuinely repriced. A component that reads the same on a quiet Tuesday and on the day the expected path shifts by a quarter point is not carrying information.
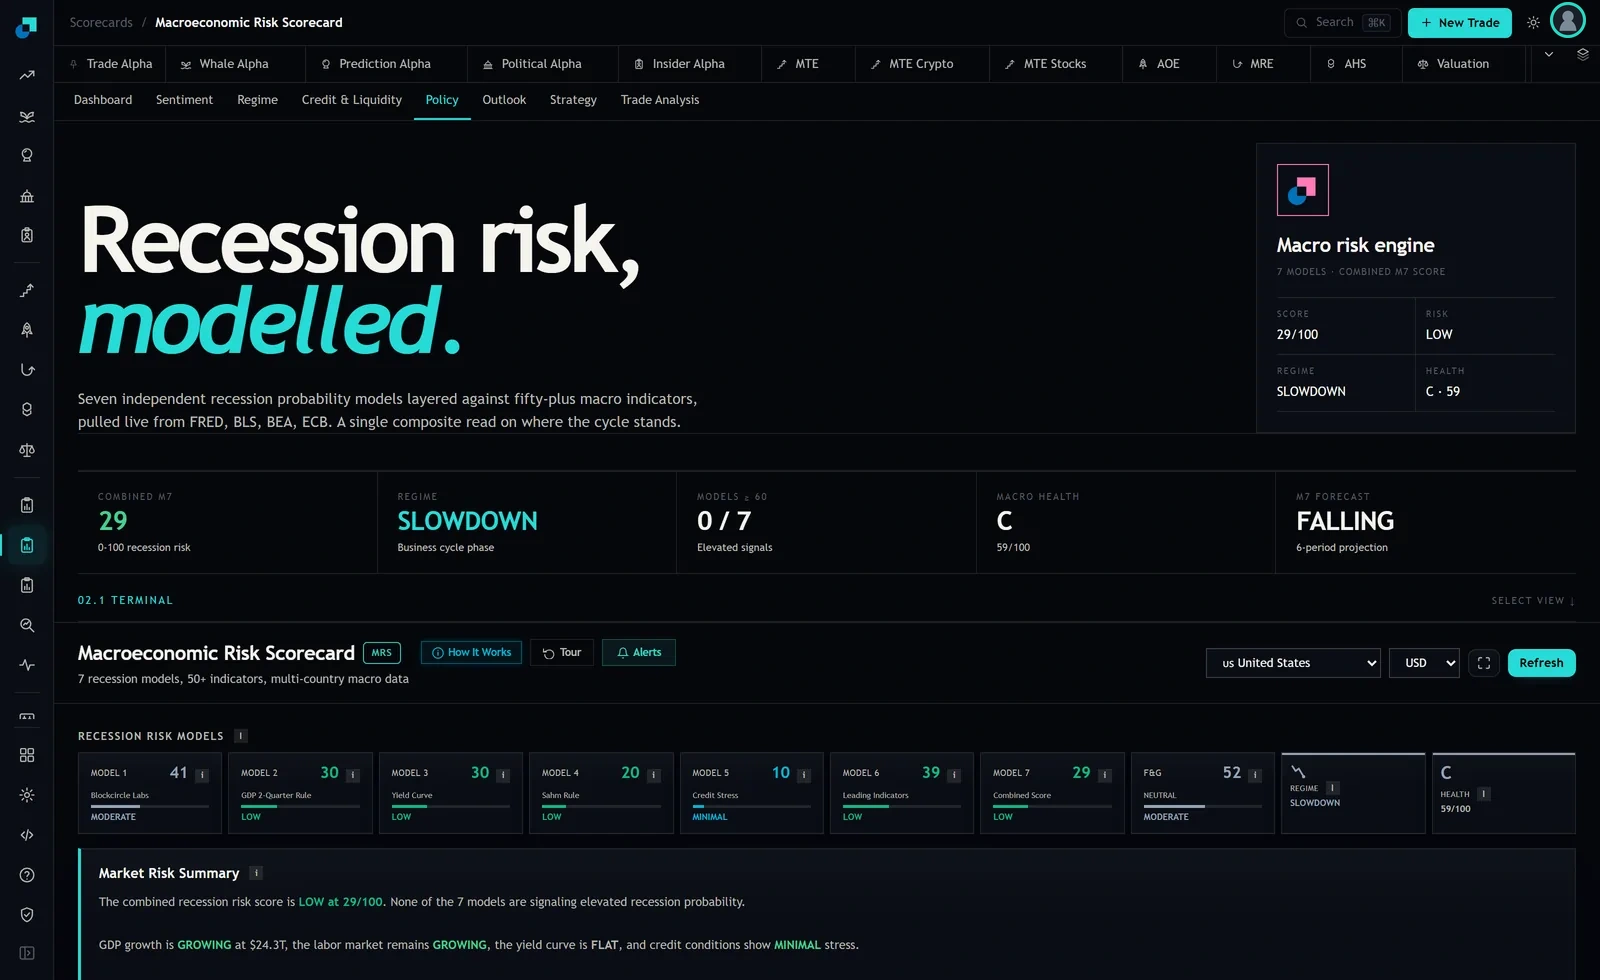
This is worth separating from what the scorecard's existing tiles do. The row currently reads Blockcircle Labs at 41, GDP two quarter rule at 30, yield curve at 30, Sahm rule at 20, credit stress at 10, leading indicators at 39 and a combined score of 29, with 0 out of 7 at or above the elevated threshold. Those are outcome models and they should keep behaving like outcome models. The surprise component is a different animal and it needs its own slot rather than a substitution.
The measurement window and what it can isolate
The construction is a change in a market-implied policy rate across a window bracketing a scheduled announcement, measured on the contracts that reference the policy rate directly rather than on longer government yields.
Window choice is the substantive decision and it is a genuine tradeoff.
- A narrow window around the release isolates the announcement cleanly, because very little other news lands in the same minutes. It also misses everything said afterwards, and on many occasions the press conference moves the path further than the statement did.
- A window extending through the press conference captures the full communication event and admits contamination from anything else that happened in that period. On a day with a major data release, the two are not separable.
- A full-day window is the easiest to compute and the least identified. It will be dominated by non-policy news often enough to matter, and it is the version most likely to produce a backtest that looks fine and fails live.
Compute at least two of these in parallel from the start. Where they agree the surprise is clean; where they diverge, that divergence is itself a flag that the day was contaminated, and marking the observation as low confidence is better than averaging over the problem.
Turning an impulse into a state variable
Here is the problem the surprise approach introduces, and it is the reason most attempts at this go wrong.
A surprise series is zero-mean by construction. Expectations are unbiased on average, so the series spends most of its life at or near zero with occasional spikes. That is fine for event studies and useless as a standing risk score, because a component that reads zero between meetings is telling a monthly investment committee nothing on the day it meets.
The fix is accumulation with decay. Maintain a running state that adds each new surprise and decays the existing stock towards zero at a fixed rate. The result is a variable that rises when a run of surprises points the same way, stays elevated while that run is recent, and fades when the market has had time to reprice. That behaviour matches the economic story, which is that repeated falsification of the expected path is a risk condition and an isolated one is not.
Fix the decay rate on stated reasoning and write the reasoning down, because it is the most consequential free parameter in the whole construction and it is the easiest to tune after the fact into whatever produced the nicest chart. My preference is to anchor it to something external, such as the horizon over which the relevant hedging activity typically completes, rather than to optimise it. Then report results under two neighbouring rates so a reviewer can see how much the conclusion depends on the choice.
The sign is not enough
A hawkish surprise is not one thing, and treating the signed magnitude as sufficient is the second common failure.
The same upward revision to the expected path can arise from two different sources. It can be a policy shock, where the committee has become less tolerant of inflation without anything having changed in the economy. Or it can carry an information component, where the committee's communication reveals that it sees the economy as stronger than the market did. Those have opposite implications for risk assets even though the measured surprise is identical.
The standard way to separate them is to look at how other assets moved in the same window. A surprise where the expected path rose and equities fell is consistent with a pure policy shock. One where the path rose and equities also rose is consistent with the communication having carried favourable news about growth. Record the co-movement alongside every surprise observation from the beginning, because reconstructing it later is tedious and the sign convention will have drifted by then.
The second refinement worth building in is the split between the immediate decision and the shape of the path further out. A surprise concentrated in the next meeting is a timing revision. One that shifts the whole path is a level revision. Score them separately, and if you can only carry one, carry the second, because timing revisions are absorbed quickly and rarely survive to the next committee meeting.
Backtesting an event component without fooling yourself
The count problem is the first thing to confront. There are only a handful of scheduled decisions a year, so a decade of history yields well under a hundred events, and the subset with large surprises is a fraction of that. Any result resting on the largest ten observations is resting on ten observations, and no amount of statistical presentation changes that.
Three rules keep the exercise honest. Use the market-implied path as it stood before each announcement, never a reconstruction from later data, since the entire measure is defined by what was priced at the time. Fix the window definition, the decay rate and the normalisation before running anything, and log any change with a date and a reason. And test whether the accumulated component adds explanatory power over the existing tiles rather than in isolation, because a component that only performs when the outcome models are already elevated has not earned a separate slot.
Then handle the scale question deliberately. If the component is to be mapped onto the same 0 to 100 range as the existing models so it reads comparably in the pack, the mapping should come from percentiles of its own accumulated history rather than from a linear rescaling, because the underlying distribution has fat tails and a linear map will park the component near the bottom of the range almost always and then jump.
Whether it belongs in the count of models at or above the elevated threshold is a separate decision from whether it belongs in the pack, and the answer to the second can be yes while the answer to the first is no. A count is a statement about independent agreement, and an event-driven component agreeing with an outcome model is a weaker statement than two outcome models agreeing. Document that distinction where the count is defined, not in a footnote nobody reads during a drawdown.