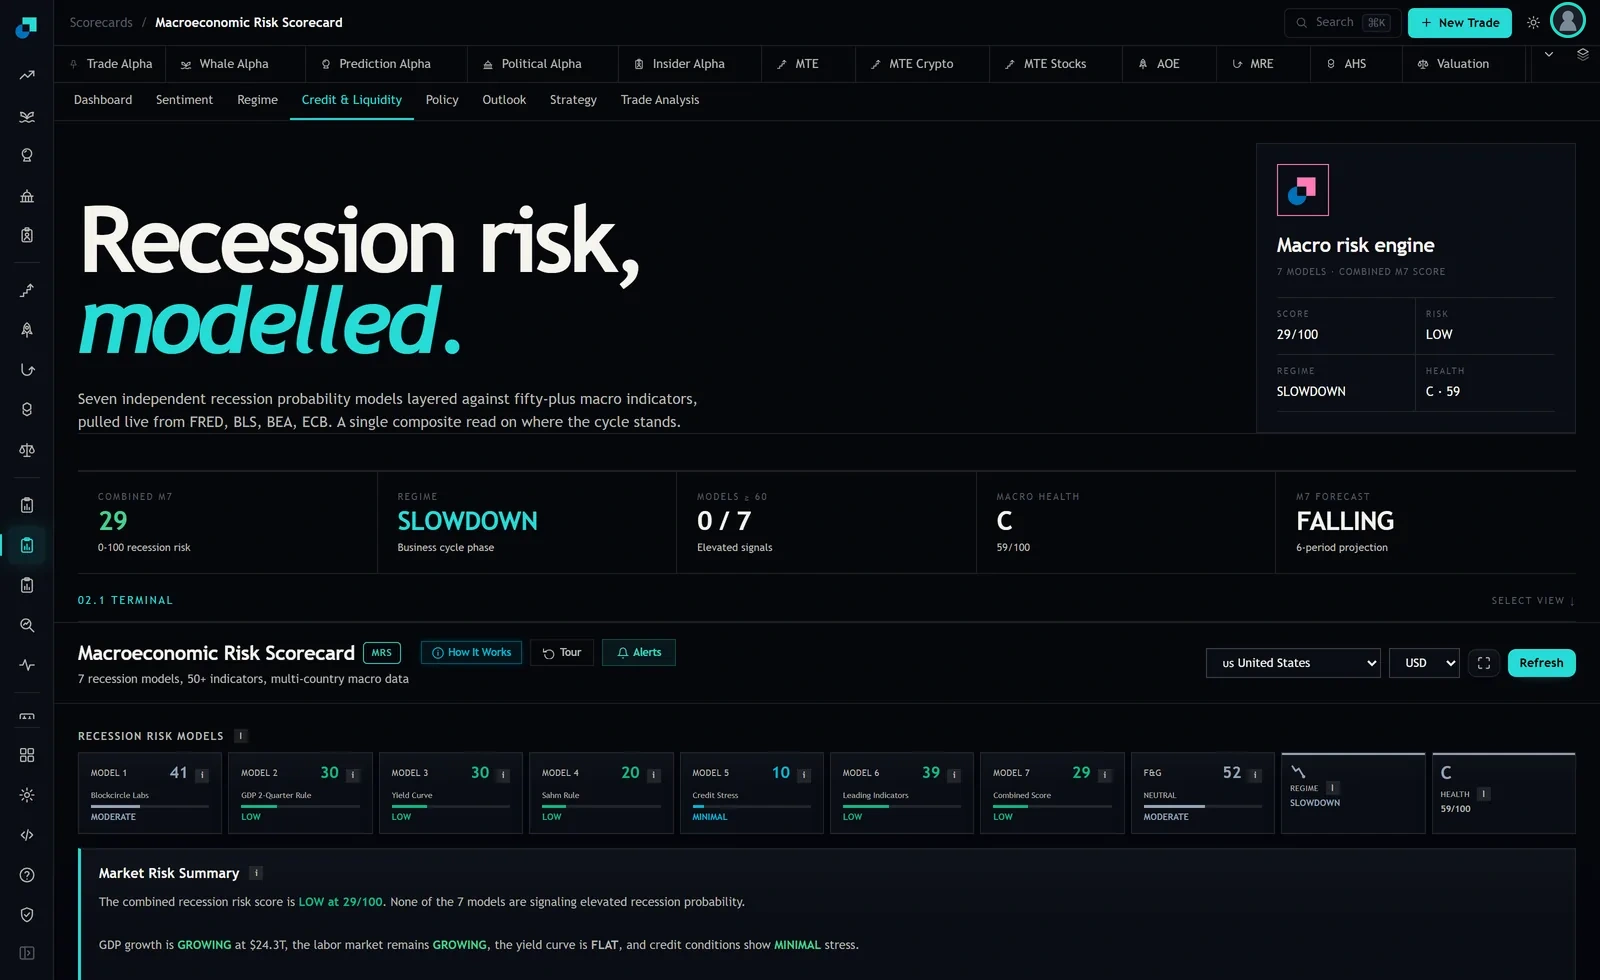
The credit node on the Macro Risk Scorecard is one tile. Model 5, Credit Stress, reads 10 out of 100 and is tagged MINIMAL, and the module describes its credit coverage as monitoring credit default swap spreads and high yield spreads alongside the dollar index and global liquidity. Everything in that description is a market price, quoted continuously.
Lending standards are not a market price. The quarterly senior loan officer surveys published by major central banks ask lenders whether they have tightened or loosened terms, which is a question about the supply of credit rather than its price, and they arrive four times a year. If you want that input in a live risk score, you are building it in yourself, and this article is about that construction rather than about a control on the page. The interesting part is not whether to include it. It is that the act of including it forces an interpolation decision, and three of the four decisions people make quietly insert information they did not have at the time.
Why a quarterly survey is worth the trouble
The case for accepting a slow input into a faster score has to be strong, and here it is specific.
Spreads tell you what the marginal buyer of existing debt demands. Lending standards tell you whether a borrower who walks into a bank can get a loan at all. Those are different mechanisms with different transmission. Credit can be repricing violently in secondary markets while banks are still lending on unchanged terms, and banks can be quietly restricting terms while the secondary market looks calm.
The second is the harder one to observe and it is closer to the real economy, because a firm that cannot roll a facility behaves differently from a firm whose bonds have widened. That is the gap the survey fills, and it is why a composite built entirely on market-priced credit has a blind spot no amount of higher frequency will close.
Four ways to fill the gap, ranked by how much they cheat
You have a series with four observations a year and a score you want to refresh monthly. Something has to fill the eight months. The options are not equally honest.
- Step function on publication date. The survey value holds constant from the day it is published until the day the next one is published. This is the only option with no look-ahead at all, because at every point in the history the value used is a value that had been published. It is also the least elegant, and it produces visible jumps in the composite on publication dates.
- Linear interpolation between observations. Draw a straight line between consecutive quarterly readings and take monthly points off it. This is the most common choice and it is disqualifying. Every interpolated point between two quarters uses the later quarter's value, which was not known at the time. A backtest built this way knows the direction of the next survey before the survey exists.
- Centred smoothing. Any moving average that is centred rather than trailing uses future observations by construction. Same defect as linear interpolation, better disguised, because the smoothing is usually applied for a legitimate-sounding reason and then nobody re-examines the window.
- Model-based interpolation from contemporaneous monthlies. Estimate the relationship between the survey and monthly series that are available in real time, then use that relationship to produce an interim estimate between publication dates. This is defensible and it is the most work, because the relationship must be estimated on data available at each point rather than on the full sample, or you have moved the look-ahead from the interpolation into the coefficients.
Ranked for most desks, the honest recommendation is the step function unless you have the infrastructure to do the fourth properly. A crude method that cannot cheat beats an elegant method that quietly does.
The look-ahead you create by accident
Beyond the interpolation choice, three alignment errors do the same damage and are easier to miss because they happen in the data plumbing rather than in the model.
The first is using the reference period instead of the publication date. A survey covering one quarter is published some weeks after that quarter ends. Stamp it to the quarter it describes and your history contains the value weeks before anyone could have read it. This single error is enough to make a mediocre input look predictive, and it is the most common defect I have seen in mixed frequency work.
The second is revision backfill. If the survey series or any series feeding your interpolation gets revised, and your database stores only the latest value, then your history is written in a data vintage that did not exist at the time. Point in time storage is the only fix, and if you do not have it, the correct move is to state the limitation in the model card rather than to report the backtest as clean.
The third is calendar alignment inside the score. If your composite is stamped at month end but one component is stamped at the following publication date, you can end up with components in the same row that were not simultaneously observable. Pick one convention, which should be a strict as-of date, and enforce it at the data layer rather than in each model.
Testing whether the input earned its place
Adding an input to a composite always improves the in-sample fit. That fact tells you nothing, so the test has to be constructed to be capable of failing.
Build the score twice, once with the survey and once without, using the step function so that neither version cheats. Then ask three questions. How many months of your sample does the survey actually change the composite by more than a trivial amount? In how many of those months did it change the decision your policy would have produced, rather than just the number? And are those months concentrated in one or two episodes?
The third question is the one that decides the matter. An input that mattered in two clustered episodes across a long sample has an effective sample size of about two, and any conclusion you draw about its value is an anecdote with a standard error you cannot compute. Adding it is then a judgement call about mechanism, which is a legitimate basis, and it should be stated as one rather than dressed up as an empirical result.
Whatever you conclude, cap the weight. A component that updates four times a year should not be capable of dominating a composite that reports continuously, and the arithmetic to prevent that is a simple ceiling on its contribution.
What goes in the model card
Everything above resolves into five lines that a reviewer can check without rebuilding the model.
State the frequency conversion method by name, and if it is the step function, say that it deliberately produces jumps at publication dates rather than treating those jumps as a defect. State the stamping convention, publication date rather than reference period, and note where the publication dates came from. State whether the underlying series is stored point in time and, if not, that the historical results include revised data. State the weight ceiling and the reasoning behind it. State the number of months in the sample where the input changed the decision, because that single figure is the most useful thing in the card and the one most likely to be omitted.
The reason to write this down is not process for its own sake. A composite like the one on this tab consolidates seven models over more than fifty indicators from FRED, the BLS, the BEA and the ECB into a combined score of 29 with a counter of models at or above 60 reading 0 out of 7. When something in a stack that deep behaves oddly, the only way anyone reconstructs why is if the frequency and vintage decisions were documented when they were made. Nobody has ever successfully reverse engineered an interpolation choice from a chart.