Any composite that sums raw on-chain activity across chains has a structural flaw baked into it before a single number is computed. Activity counts are denominated in units whose price differs by orders of magnitude between chains, so the chain with the cheapest blockspace contributes the most volume for the least economic content. Aggregate without deflating and the composite becomes, in large part, a ranking of who subsidised throughput hardest.
This is not a hypothetical failure. It is the default outcome of the obvious construction, and it gets worse over time, because the cheapest chain in the set keeps getting cheaper while the expensive one does not.
What the composite in front of you is made of
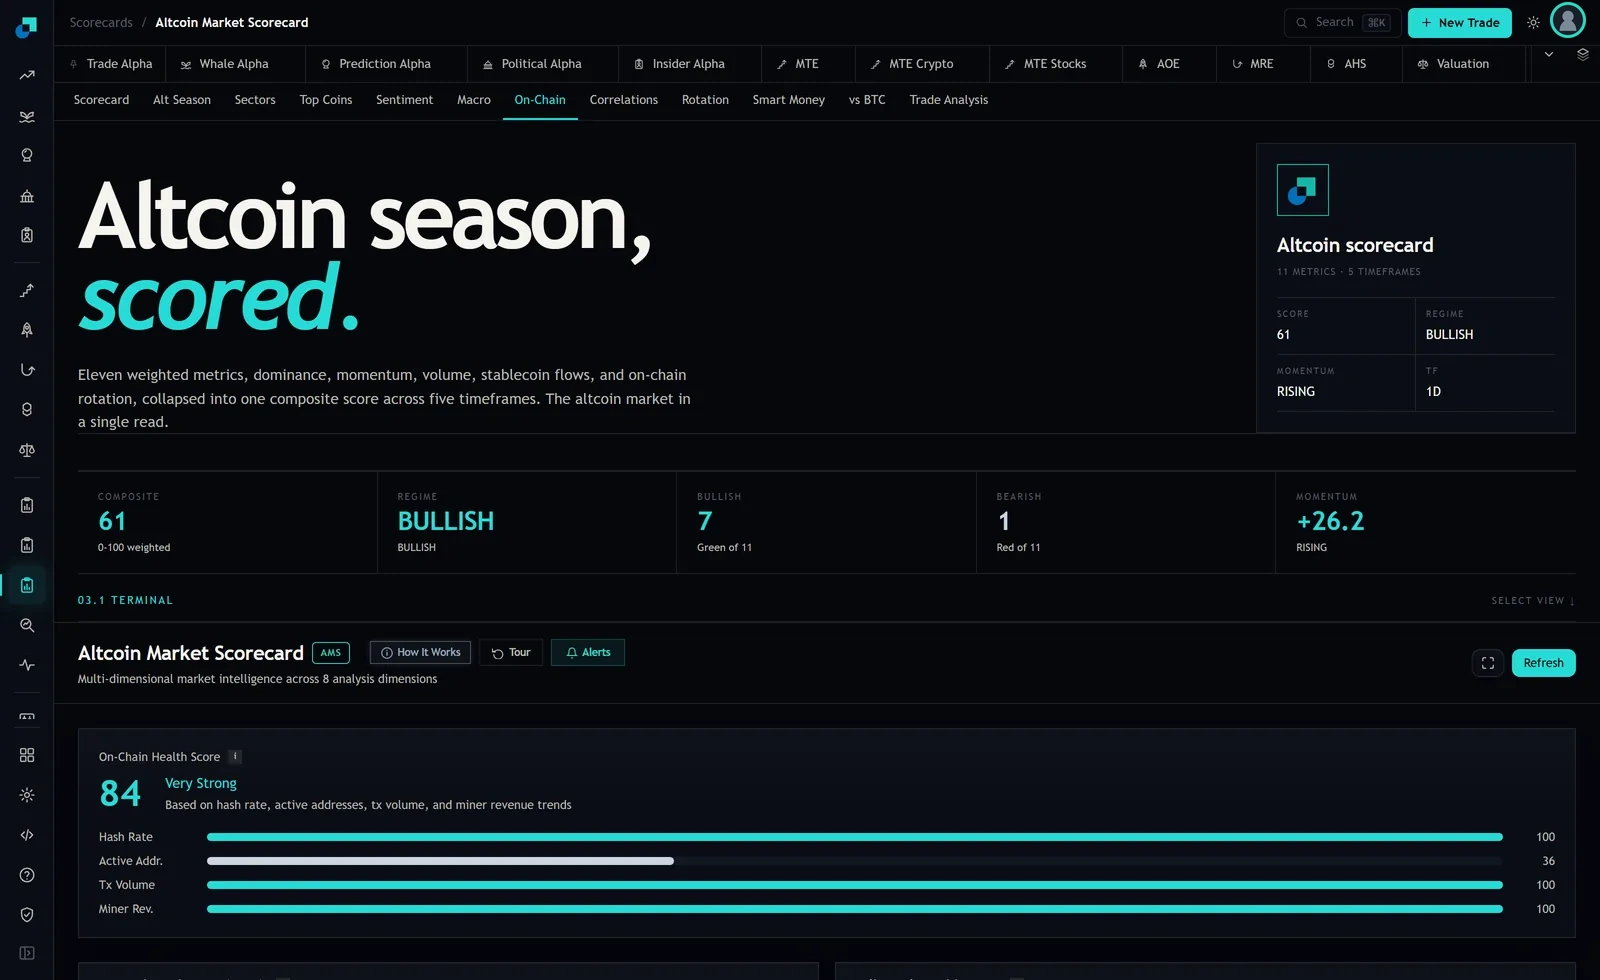
The On-Chain tab presents a health score of 84 with the label Very Strong, described as based on hash rate, active addresses, transaction volume and miner revenue trends. The four component bars read Hash Rate 100, Active Addr. 36, Tx Volume 100 and Miner Rev. 100.
Two observations before any methodology work. First, three of four inputs are pinned at the top of their normalised range, so the composite's current variation comes almost entirely from one input, and a composite whose movement depends on a single component is a single component wearing a composite's name.
Second, and more relevant here, hash rate and miner revenue are proof of work quantities. As labelled, this health read is shaped around a mining chain. The scorecard it sits inside is about altcoins, a large share of which have no miners and no hash rate at all. The panel does not expose a per-chain breakdown, so I cannot tell you what the coverage set is or how it is combined, and I am not going to guess. What I can say is that the input names tell you the construction is chain-specific in character, and that is exactly the situation in which a cross-chain normalisation layer has to be built somewhere, whether inside the vendor or inside your own stack.
The deflators, and what each one removes
Four adjustments, in the order they matter. Each one is designed to strip out a specific mechanical advantage that has nothing to do with demand.
The unit-cost deflator, for counts. Divide a chain's transaction count by nothing and you are measuring blockspace price. Instead, express throughput in economic terms: multiply the count by the chain's own median fee, or equivalently work directly with fee revenue rather than with the count. A chain that processes a hundred times as many transactions at a hundredth of the fee should not contribute a hundred times as much to an activity aggregate, and after this step it does not.
The fee-level deflator, for revenue. Absolute fee revenue rewards congestion, which is the opposite of what you usually want to reward. Normalise each chain's fee revenue by its own trailing median, so the input becomes the change in demand for that chain's blockspace rather than the level of its price. This is the step that stops a fee spike on one expensive chain from being read as market-wide strength.
The address deflator, for participation. Address counts are the cheapest thing on any chain to manufacture and the cost of manufacturing them differs by chain. Deflate by a density measure, such as value or fee revenue per active address, so a chain that adds a million addresses that each pay nothing does not register as a million new participants.
Within-chain standardisation, before aggregation. Convert each deflated metric to a z-score against that chain's own trailing distribution, then combine across chains. The point is that after this step a chain's scale can no longer set its weight in the composite, because every chain is contributing a standardised deviation from its own history rather than a raw quantity. This single step removes most of the mechanical capture even if the first three are done crudely.
Weighting chains once the units are comparable
Standardisation makes the inputs comparable, it does not decide their weights, and that is a separate choice with real consequences.
Equal weight across chains gives you a breadth read. It answers whether activity is improving across the ecosystem, and it will be dominated by small chains in the sense that a small chain's improvement counts as much as a large one's. That is either the feature or the bug, depending on what the score is for.
Capitalisation weight gives you a read that tracks where value sits, which is the appropriate choice if the composite is an input to sizing an investable sleeve. Its weakness is that it inherits whatever concentration the market has, and in practice that means one or two chains decide the number.
Economic-activity weight, using deflated fee revenue as the weight itself, is the middle option and often the most defensible for a demand read, because a chain's influence on the score becomes proportional to what users actually pay it. It is also the one that needs the tightest revision controls, since the weights move with the same data that drives the score.
Whichever you pick, cap it. An uncapped cross-chain composite in this market is a single-chain series with extra steps.
The before-and-after I cannot show you, and what replaces it
The natural way to end this would be a table showing the composite before normalisation and after. I cannot produce one, and it is worth being explicit about why rather than filling the gap with something plausible. The panel exposes a single blended score and four component bars. It does not expose per-chain inputs, coverage, or weights, so there is nothing in the display to recompute from. Any before-and-after I published would be a simulation of a pipeline I cannot see.
What you can do inside your own stack is a contribution decomposition, and you should build it at the same time as the composite rather than afterwards. For each period, attribute the change in the composite to each chain and each input, so that every move has an answer to the question of who caused it. Then the normalisation question stops being theoretical: you look at last quarter's decomposition and see immediately whether one chain supplied most of the movement, and whether that chain is the cheap one.
Three tests that catch blockspace capture
Run these quarterly and keep the results, because they are also the evidence you will want in a methodology review.
First, the drop-one-chain test. Recompute the composite excluding each chain in turn. If removing one chain changes the level or the sign of the trend materially, your aggregate is that chain and the normalisation has failed regardless of how sound it looks on paper.
Second, the cheap-chain correlation. Correlate the composite against the raw, undeflated transaction count of the cheapest chain in the set. A high correlation is the direct diagnostic for capture, and it is the fastest of the three to compute.
Third, the fee-regime step test. When a chain changes its fee market, through an upgrade, a parameter change or a new rollup pricing scheme, look at the composite across that date. A properly deflated composite should not step. If it does, the change in the price of blockspace is being read as a change in demand for it, which is precisely the error the whole exercise exists to prevent.
What the methodology appendix has to say
Six lines, and they are the difference between a defensible composite and an opinion with decimals: the chain coverage set and the date each chain entered it, the deflator applied to each input with its formula, the standardisation window, the chain weighting scheme and any cap, the revision policy for the underlying series, and the date of the most recent drop-one and fee-regime test with their results. If the composite is sourced rather than built, that appendix is the list of questions to put to the provider, and an inability to answer the first two is itself an answer.