Rare classes are the most seductive rows in any regime table. They carry the highest headline win rates, the largest best-case figures, and the smallest sample counts, and those three facts are the same fact. The row looks like a discovery because almost nothing has had a chance to contradict it.
The right response is neither to trade it nor to delete it. It is to shrink it, deliberately, with a weight you can write down and defend in a review.
What the capture supports before I go further
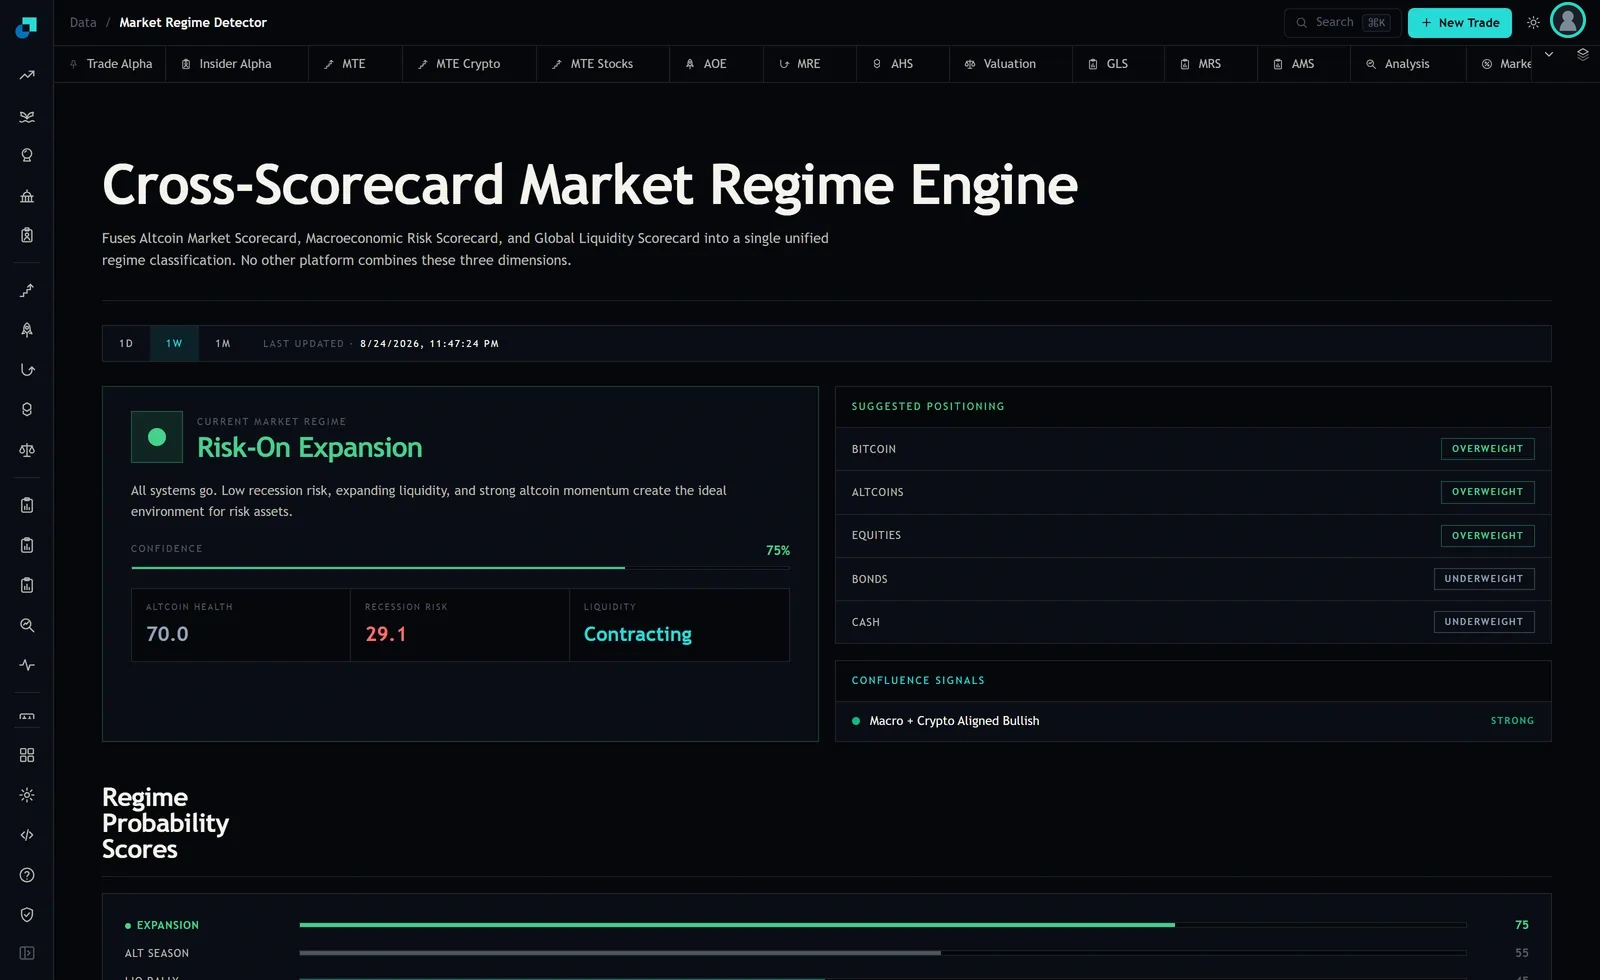
The Market Regime Detector capture I am working from does not include a per-regime distribution table. It shows the current classification of Risk-On Expansion at 75 percent confidence, the component readings behind it, and score bars reading Expansion 75, Alt Season 55 and Liq Rally 45. There are no historical period counts, no per-class win rates and no per-class return figures anywhere in it.
So I am not quoting a sample size for any regime. What the capture does establish is why thin classes are inevitable in a model of this shape. The engine fuses three scorecards, the Altcoin Market Scorecard, the Macroeconomic Risk Scorecard and the Global Liquidity Scorecard, into one classification. Any taxonomy built by thresholding three continuous inputs will place some labels in corner regions of the input space, and corners are small. A class that requires an unusual joint configuration of all three inputs will be rare no matter how long the history is, and no amount of additional data will make it common.
The resolution four observations actually gives you
Work the numbers before deciding what a thin row is worth, because the intuition is badly wrong and the arithmetic takes a minute.
Take a win rate on four periods. The standard error at a true rate near one half is the square root of a quarter over four, which is 0.25. Twenty five percentage points. A one standard error band on that estimate covers half the available range, so a class showing three wins from four is statistically indistinguishable from a coin.
Now take the strongest possible result, four wins from four. Ask what true hit rate would produce that outcome at least five percent of the time. The answer is the fourth root of 0.05, which is about 0.47. A perfect record over four periods is consistent with a true hit rate slightly below a coin flip. That single number is the most useful thing in this article and I would put it on the wall.
Mean returns are no better. The standard error of a mean over four observations is the period volatility divided by two. If periods carry an eight percentage point standard deviation, the standard error on the class mean is four points, so a class mean of six percent sits about one and a half standard errors from zero and would not survive any test you would apply to a live strategy.
The shrinkage weight, written out
Shrinkage replaces the class estimate with a weighted blend of the class estimate and the pooled estimate across all classes. The whole method reduces to how you set the weight, and the empirical Bayes form is short enough to compute in a spreadsheet.
Let tau squared be the variance of the true means across classes, meaning the genuine spread you believe exists between regimes. Let sigma squared be the within-class variance of period outcomes, and let n be the number of periods in the class. The weight on the class estimate is tau squared divided by the sum of tau squared and sigma squared over n. Everything else goes on the pooled mean.
Put numbers in it. Suppose the genuine spread between regime means is on the order of three percentage points, so tau squared is 9. Suppose period volatility is eight points, so sigma squared is 64. For a class with four periods, sigma squared over n is 16, and the weight lands at 9 divided by 25, or 0.36. A class mean of six percent against a pooled mean of two percent shrinks to roughly 3.4 percent. Nearly two thirds of the apparent edge disappears, and that is the correct outcome rather than a conservatism adjustment.
Run the same weight for a class with forty periods and sigma squared over n is 1.6, giving a weight of about 0.85. That contrast is the entire point of the exercise. The method does not distrust rare regimes because they are rare, it distrusts them in exact proportion to how little they have had the chance to say.
Estimating tau is the only judgement call, and there is a defensible way to do it rather than guessing. Compute the observed variance of class means, then subtract the average sampling variance across classes, and floor the result at zero. If that subtraction leaves you at or near zero, the honest conclusion is that the observed dispersion between regimes is entirely explained by sampling noise, and every class estimate should shrink almost all the way to the pooled mean.
The best-case column belongs in no ranking
Any per-regime table that carries a maximum or best-case return needs a warning attached, because a maximum is a biased estimator whose bias grows with sample size. Draw four observations from any distribution with a tail and you will see a smaller maximum than if you draw two hundred from the same distribution, for reasons that have nothing to do with the regimes being different.
So sorting classes by best case sorts them substantially by how many periods they contain. It is not a performance ranking and it should never enter a sizing decision.
The related trap runs the other way. If a thin class shows an average return large enough to be startling, do not repeat the figure. On a handful of periods, a headline like that is usually one outlier period dominating the mean, or a compounding convention applied to a short window and then presented at an annual rate, and it will not reproduce. Trace it to the underlying periods, and if you cannot, leave it out of the document entirely. A number you cannot explain the construction of is a liability in a review, not evidence.
Turning the weight into an allocation rather than a footnote
Shrinkage usually stops at the reporting layer, which wastes it. The weight is a sizing instrument and it does the job cleanly.
Scale the tilt by the weight itself. If your process would put a full tilt behind a well-populated regime, put 0.36 of that tilt behind a four-period regime with the parameters above. The allocation then moves continuously with evidence instead of switching on at some arbitrary minimum sample count, and the rule survives the case everybody argues about, which is the class sitting just below whatever threshold somebody wrote down.
Two things belong in the process document alongside it. First, report the raw class estimate, the pooled estimate, the weight and the shrunk estimate together, always as a set of four. A shrunk number presented alone looks like a measurement and hides the fact that most of it came from the pool. Second, publish the period count for every class in every table, in the first column rather than the last, because the count is what determines how much of the rest of the row you are entitled to believe.