A cluster card is a persuasive object. It puts a ticker at the top, a member count under it, a date window under that, and then the individual names in a table, and the visual grammar of the thing says these people acted together. Sometimes they did. Most of the time what you are looking at is the arithmetic of a busy filing calendar meeting a stock that a lot of people own.
The discipline that separates the two is boring and it is the only thing that works. Compute how many co-occurrences you would expect by chance, and only treat the excess as information. Until you have that number, a cluster of three tells you nothing, because you do not know whether three is remarkable or whether three is Tuesday.
What the card asserts and what it leaves unlabelled
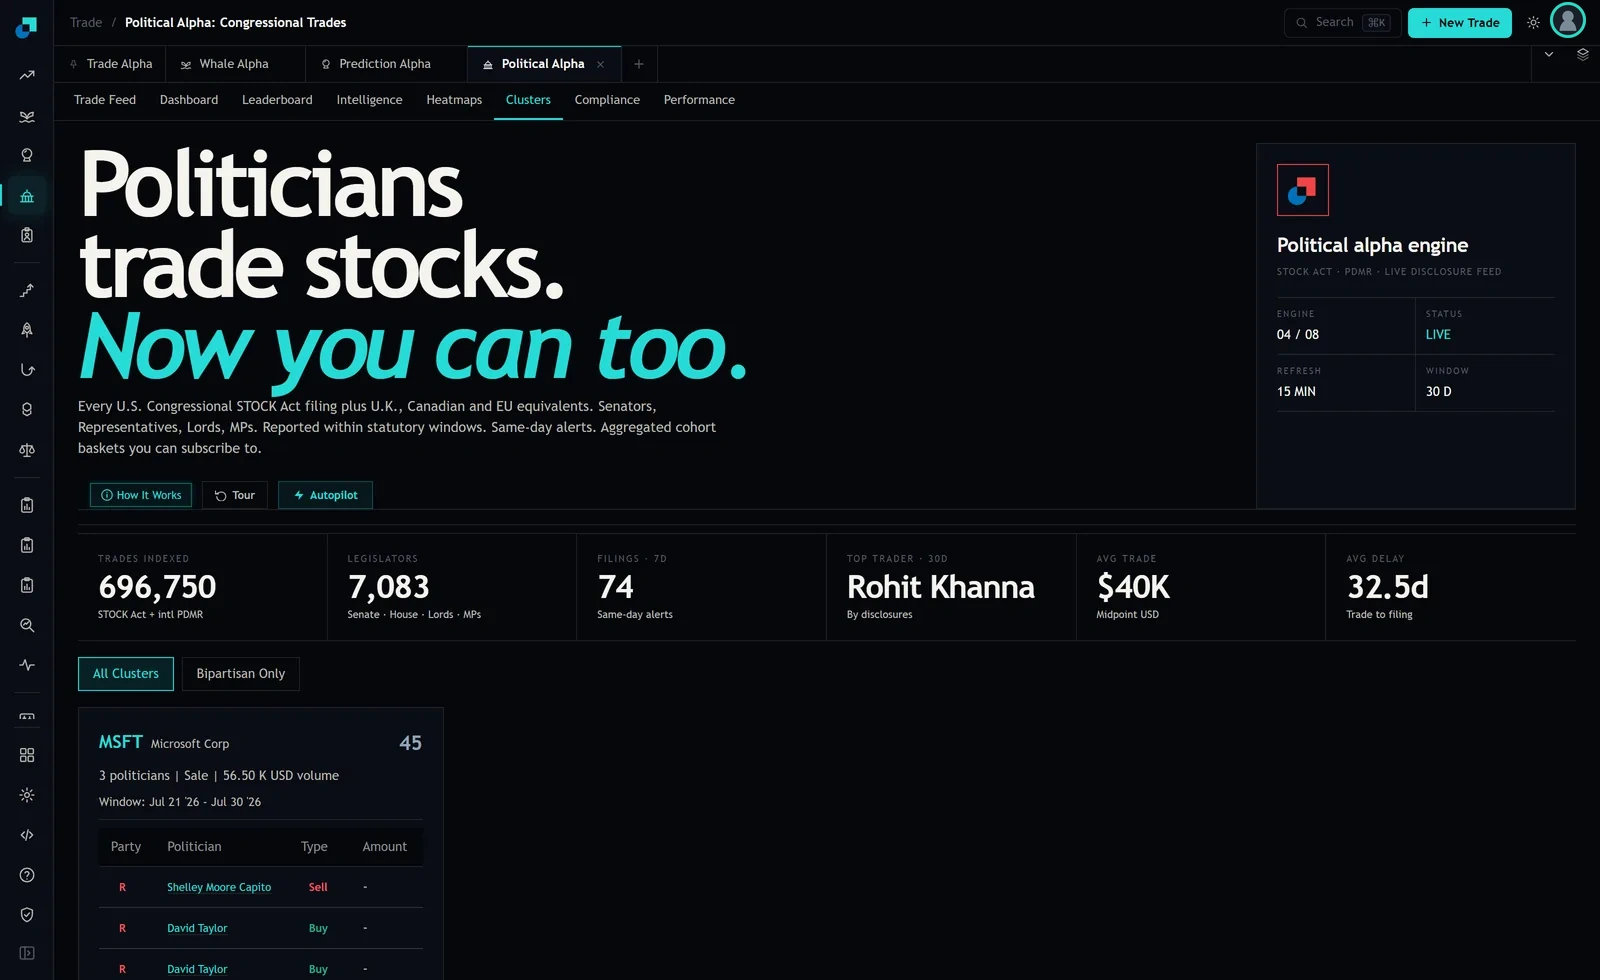
The Clusters tab opens with two view buttons, All Clusters and Bipartisan Only. Each card carries the ticker and company name, a bare number in the top right corner, a summary line reading member count, direction and USD volume, a window with explicit start and end dates, and then a table with columns Party, Politician, Type and Amount.
On the card in front of me that reads: Microsoft, 45 in the corner, three politicians, Sale, 56.50 K USD volume, window of ten days. The rows underneath carry a party letter, a name, a Buy or Sell type and an amount.
Three things about that construction matter for a significance test. The corner number is unlabelled, so I do not know what it scores or how it is scaled, and I am not going to treat it as a p-value or as a confidence measure just because it is a number in a prominent position. The direction on the summary line reads Sale while the visible rows include both Sell and Buy, so the header direction is a summary of a mixed group rather than a description of every row. And the Amount column reads as a dash on those rows, which means per-row size is not always populated even though the card reports a group volume.
Building the null from arrival rates
The null model you need answers one question. If members filed exactly as often as they actually do, and chose tickers exactly as often as they actually do, but chose them independently of each other, how many would land on this ticker inside this window?
Start with the arrival rate. The module header reports 74 filings over seven days, and that counter is explicitly labelled same-day alerts, so treat it as a lower bound on total filing traffic rather than the whole flow. Seventy four over seven days is about 10.6 a day. The cluster window on this card runs ten days, so the expected filing count inside it is roughly 106, again as a floor.
Now the ticker distribution. You need the share of equity filings that land on the ticker in question, estimated over a long history rather than over the window you are testing, because using the window itself to estimate its own null is how you guarantee a significant result. Suppose a mega-cap widely held across the membership takes 3 percent of equity filings. Then the expected count on that ticker in a ten day window is 106 times 0.03, which is a little over three.
Three expected. Three observed. That cluster is not evidence of anything. It is the arrival rate.
The general form is the same each time. Expected co-occurrences equal filing rate times window length times ticker share, and because filings are approximately independent arrivals you can take the observed count as Poisson around that expectation. A count of three against an expectation of three has a one-sided tail probability near a half. A count of eight against an expectation of three sits out near the two percent mark. That gap between three and eight is the entire content of the test, and eyeballing a card cannot tell you which side of it you are on.
Index membership is the term people forget
The ticker share is not a nuisance parameter. It is the dominant term, and it is driven by something that has nothing to do with information.
Members and their households hold the same things everyone else holds, which means index constituents, and the largest index constituents most of all. The heatmap tiles show the same pattern from the other direction, with leading names in Information Technology reading GEN, IT, ORCL, QCOM, QLYS and in Financials FISV, COIN, UPST, ARCC, CME. These are not obscure situations. A ticker that sits in every target date fund in America will produce co-occurrences at a high base rate forever, and the more prominent the name, the higher the bar a cluster on it has to clear.
The practical consequence is that your null has to be per-ticker, not global. A global average share applied to a mega-cap will understate the expectation badly and hand you a stream of false positives on exactly the names where a cluster means least. Conversely, three members landing on a small cap that takes 0.05 percent of filings has an expectation near 0.05 and an observed count of three, which is genuinely extraordinary and is the kind of card worth an hour of work.
So build the share estimate from your own history of the feed, ticker by ticker, over a long trailing period, and refresh it quarterly. The module indexes 696,750 trades across 7,083 legislators, which is more than enough to estimate a stable share for any ticker that appears often enough to form clusters in the first place.
The multiple comparisons problem is bigger than the test
Here is the part that quietly destroys most cluster research. You are not testing one cluster. The tab is scanning every ticker in the universe, every day, and surfacing the ones that look unusual. If you evaluate the survivors at a five percent threshold, you will accept a large number of pure coincidences, because a screen that examines a thousand names a week produces fifty five percent tail events a week with no information present at all.
Fix it explicitly rather than by intuition. Decide how many independent ticker-window combinations the screen effectively examines, then set your per-cluster threshold to your desired family rate divided by that number. In practice this pushes the bar from a two percent tail to something several times tighter, and it means the ordinary three-member card on a common name will essentially never clear it. That is the correct outcome and you should expect the screen to produce very few survivors. If it produces many, your ticker shares are wrong.
Add one more filter that costs nothing. Deduplicate by member before counting, because a single member filing the same ticker twice inflates the row count without adding an independent observation. The card in front of me shows exactly that pattern, with one name on two of the three visible rows, and a co-occurrence count that treats those as two observations is measuring one person's paperwork.
What a cluster has to look like to survive
Put the pieces together and the surviving population has a recognisable shape. Distinct members rather than repeat rows. A ticker with a low filing share, which in practice means outside the mega-cap complex. A count several times the Poisson expectation rather than one or two above it. A single direction across the members, since a card whose summary reads Sale while its rows contain both buys and sells is two groups drawn on one border. And a window tight enough that the members plausibly acted on the same information rather than on the same calendar quarter.
Everything else goes in the log and nowhere else. The value of running the null is not that it finds you more signals, it is that it stops you spending research capacity on cards that are arithmetic, and it gives you a defensible sentence for the review when someone asks why the desk ignored a cluster that later moved. The answer, that the observed count was inside the expected range for that ticker at that filing rate, is a much better answer than a shrug.